Search result · source text not verified
sambanova: products, features, and independent customer feedback.
Products
DataflowThe natural movement of AI.
SambaNova’s Dataflow Architecture is a hardware design in its Reconfigurable Dataflow Unit (RDU) that allows data to flow from one AI operation to the next as an assembly pipeline. This architecture eliminates frequent, energy-intensive memory bottlenecks (kernel calls), enabling faster AI inference, higher model utilization, and significantly better energy efficiency. Source ↗
SambaCloudThe fastest AI inference on the largest models.
SambaCloud is a full-stack AI inference platform developed by SambaNova. It delivers the fastest inference speeds on large open-source models — including Llama, DeepSeek, and Qwen — using SambaNova's proprietary Reconfigurable Dataflow Unit (RDU) AI chip. It is purpose-built for developers who need high-throughput, low-latency AI at scale. Source ↗
SambaRackAir-cooled hardware built for cloud-scale agentic AI solutions.
SambaRack is a turnkey AI rack system designed to deploy and run large AI models efficiently in data centers. It integrates hardware, networking, and software into a single self-contained system built around SambaNova RDU chips to deliver fast inference performance. Source ↗
SambaStackThe most efficient full-stack fast AI inference to build your AI factory.
SambaStack is SambaNova's full-stack enterprise AI platform, combining purpose-built hardware and software into a single, integrated solution for AI inference. It is designed for organizations that need dedicated AI infrastructure — deployed either on-premises or in the cloud — and want to run the fastest inference on leading open-source models at scale. Source ↗
SambaStack allows your team to fully configure the workloads you want to run on SambaRack systems. Each rack can run pre-configured model bundles and hot-swap between model bundles at inference time. This allows you to serve more models with a significantly smaller hardware footprint. Source ↗
RDURDU chips from SambaNova are purpose-built for agentic inference. The SN50 is the chip with the speed and throughput required for agentic AI.
No matching products or features.
Customer feedback
Search result · source text not verified
Intel-Backed AI Chip Firm SambaNova to Quintuple Valuation to $10 Billion
@MiniMax_AI @SambaNovaAI I’m cancelling my subscription, and I’ll make sure everyone I know stays away from your service. This has been a terrible experience, and I’m done wasting my time and money on something this unreliable.
Search result · source text not verified
Intel in talks to acquire AI startup Sambanova Systems
Search result · source text not verified
SambaNova (sambanova.ai) – TIL about this competitor
Search result · source text not verified
Any info on Sambanova? : r/Theranos
https://venturebeat.com/ai/sambanova-announces-new-ai-samba-coe-v0-2-that-already-beats-databricks-dbrx/ https://techcrunch.com/2023/09/19/new-sambanova-chip-d ...
Search result · source text not verified
Sambanova interview or Scam? : r/csMajors
The email is from the domain: sambanova.live Hi, Welcome to SambaNova. We recently looked over your background and we think you will be a good fit as ...
Search result · source text not verified
SambaNova SN50 benchmarks - does anyone have hands ...
SambaNova SN50 benchmarks - does anyone have hands-on time with this? Discussion.
Search result · source text not verified
A Conversation with AI Visionaries from SambaNova ...
Dataflow-as-a-Service takes SambaNova's expertise and learning and adds that to the client's team. The service allows our clients to run ...
Search result · source text not verified
The first valuable comment imho, thanks! Let me add
https://sambanova.ai/ (Enterprise AI and dataflow-as-a-service for established models) ; https://www.cerebras.net/ (AI accelerator, trying to compete with Nvidia).
Search result · source text not verified
OpenAI is exploring making its own AI chips
- https://sambanova.ai/ (Enterprise AI and dataflow-as-a-service for established models). - ... A story like this could also help negotiate prices ...
No feedback found.
Marketing & Ads
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Oct 6, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Oct 6, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInSambaNova
Original ad ↗
Talk To Our Neocloud Team To See How You Could Benefit
You can serve a billion tokens a second and lose money on every one of them. Speed is expected. Payback is the benchmark. Ours is 6 months. Here’s a fun experiment for you: Ask an AI infrastructure vendor about payback and watch how quickly the conversation gets awkward. 😬 Every buyer cares about one thing: When does this hardware earn back what I paid for it? For most infrastructure, the answer is a year or more. We’ve somehow decided that’s normal. Well, we don’t. 6-month payback. 5-year lifespan. You can do the math. Economics is the real difference-maker.
Request Demo
First shown Oct 19, 2026 · Last shown Nov 11, 2026
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Oct 14, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInSambaNova
Original ad ↗
Making AI More Affordable with Disaggregated Inference
"As the cost of tokens continue to rise because the infrastructure is so expensive, people are looking for alternatives. So at SambaNova, we come in with a much lower-cost infrastructure, much higher performance. We drive it at 10 kilowatts, an order of magnitude lower power than the traditional GPUs." — Rodrigo Liang During his chat with Matthew Miller on Bloomberg Television, Rodrigo explained how we're able to make AI more affordable: disaggregated inference. Instead of relying on a single architecture, it combines GPUs for prefill, RDUs for high-speed decode, and CPUs for orchestration, allowing each processor to do what it does best. The result is faster inference, lower latency, and significantly lower-cost tokens for enterprises and service providers deploying AI at scale. This architecture powers the world's first commercially available disaggregated inference cloud, including VC2, helping organizations bring AI into production with better performance and better economics. Watch their conversation below ⬇️
Learn more
First shown Sep 15, 2026 · Last shown Nov 11, 2026
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Oct 6, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Oct 6, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInSambaNova
Original ad ↗
LIVE from Oracle AI World 🚨 SambaNova and Oracle are collaborating to bring high-performance inference to Oracle Cloud Infrastructure (OCI). “Our customers want the right infrastructure for every AI workload, and inference demand is growing fast,” said Mahesh Thiagarajan, President, Oracle Cloud Infrastructure. “We plan to bring SambaNova’s RDU chips to OCI to give AI builders a high-performance, efficient way to run models at scale.” Link to the full press release in the comments below ⬇️
Landing page unavailable: the ad source did not supply a destination URL.
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Oct 6, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Oct 6, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Oct 6, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInSambaNova
Original ad ↗
Broadcom's Charlie Kawwas & BlackRock's Tony Kim on Best Inference Platforms
When you get a haute couture shoutout at RAISE Summit 🤩 Huge thanks to Charlie Kawwas & Tony Kim for highlighting the amazing collaboration between our teams across generations of AI infrastructure. So inspiring to watch heterogeneous AI infrastructure lead the way as we move into an exciting new chapter for enterprise AI! 🦾 Rodrigo Liang Henri Delahaye Broadcom BlackRock
Learn more
First shown Sep 15, 2026 · Last shown Nov 11, 2026
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Oct 6, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Oct 6, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInSambaNova
Original ad ↗
The Power Crisis No One Is Talking About in AI
"The benefit of SambaNova, uniquely, which is a result of our architecture, is our systems are fully air cooled. They're 30 kilowatts and they can go into most datacenters in the world today." — Anton McGonnell Many AI racks need 600 kW of power. No datacenter in the world can handle that today. SambaNova runs on 30kW and fits in existing infrastructure. 🦾 🎥: Forbes
Learn more
First shown Sep 15, 2026 · Last shown Nov 11, 2026
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Sep 16, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Sep 16, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Sep 16, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInSambaNova
Original ad ↗
Talk To Our Neocloud Team To See How You Could Benefit
You can serve a billion tokens a second and lose money on every one of them. Speed is expected. Payback is the benchmark. Ours is 6 months. Here’s a fun experiment for you: Ask an AI infrastructure vendor about payback and watch how quickly the conversation gets awkward. 😬 Every buyer cares about one thing: When does this hardware earn back what I paid for it? For most infrastructure, the answer is a year or more. We’ve somehow decided that’s normal. Well, we don’t. 6-month payback. 5-year lifespan. You can do the math. Economics is the real difference-maker.
Request Demo
First shown Oct 19, 2026 · Last shown Nov 11, 2026
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Sep 20, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Sep 20, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleSambaNova Systems, Inc
Original ad ↗ First shown Sep 20, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInSambaNova
Original ad ↗
Big news for our team: SambaNova Co-Founder and CEO Rodrigo Liang has joined the WSJ Leadership Institute CEO Council. Rodrigo brings decades of experience building processors, systems and technology designed for the world’s most demanding computing challenges. At SambaNova, that vision has driven a full-stack approach to AI infrastructure built around our Reconfigurable Dataflow Unit architecture. As AI moves from experimentation to production, Rodrigo brings a clear perspective on what it will take to deliver inference faster, more efficiently and at an economic scale. We’re looking forward to the conversations ahead. Congratulations, Rodrigo! 🚀 Learn more: https://bit.ly/4xJRxE3
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInSambaNova
Original ad ↗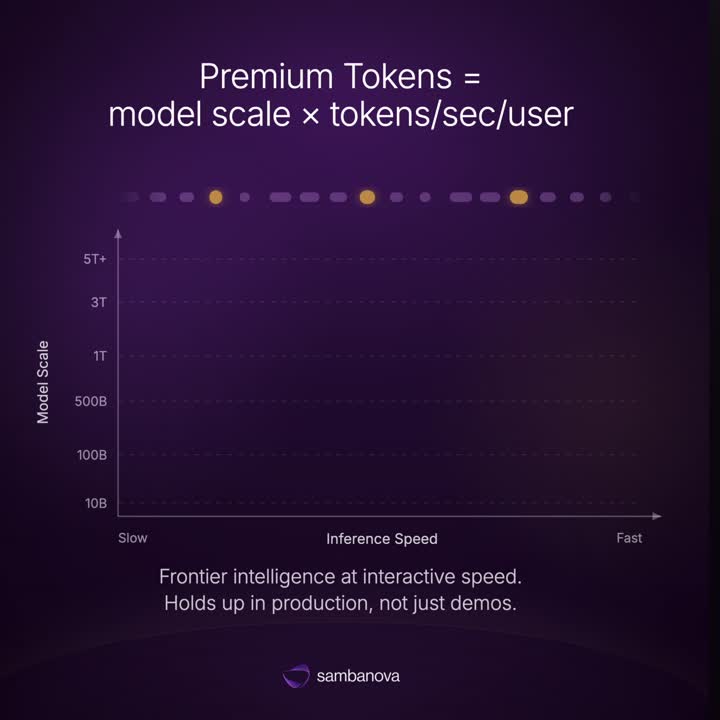
The Premium Inference Moment Is Here
What happens when bigger, smarter models also get faster? 🤔 You get a new category of AI experience: premium inference. As models scale, speed becomes just as important as intelligence. For agents and other latency-sensitive workloads, every token matters. The next step isn't just serving more tokens. It's serving better tokens, faster.
Learn more
First shown Sep 15, 2026 · Last shown Nov 11, 2026
Website marketing
Contact SambaNova Today ↗
Connect with SambaNova. Contact us for sales inquiries, partnerships, technical support, or general information about our AI solutions and platform.
Observed Nov 11, 2026
New pages
Rodrigo Liang on AI Inference Economics and ROI at CAIS | SambaNova ↗
On-Premises AI Inference Behind the Firewall | SambaNova ↗
Inference Is the Center of the AI Economy | Rodrigo Liang, SambaNova ↗
RDU Dataflow Architecture: Faster AI Inference | SambaNova ↗
Published Source ↗
Argonne National Laboratory Scales Agentic AI with SambaStack ↗
TACC Accelerates Open Science with SambaStack ↗
How TACC Runs On-Premises AI Research on SambaStack ↗
General Compute builds the world’s fastest inference cloud with SambaNova ↗
Ricoh runs Japanese custom AI models 10× faster on SambaCloud ↗
How to Build a ReAct AI Agent with LangGraph ↗
Delivering Sovereign AI to the EU ↗
The Rise of Deep Agents and Coding Agents ↗
Do More with Less: Enterprise Agent Tech Workflows on Minimal Hardware ↗
Context Engineering for AI Agents: A Guide ↗
OVHcloud Premium AI Endpoints Powered by SambaNova ↗
Infercom x SambaNova | Sovereign AI Inference in Germany ↗
Modified Source ↗
supermicro will build and sell sambanova powered inference systems ↗
Modified Source ↗
sambanova and supermicro partnership ↗
Modified Source ↗
Size Your AI Deployment ↗
Modified Source ↗
Team ↗
Modified Source ↗
team ↗
Modified Source ↗
Fast, secure AI inference for mission-critical government workloads ↗
Modified Source ↗
Events ↗
Modified Source ↗
sambanova and emergys partner to accelerate enterprise agentic ai deployment ↗
Modified Source ↗
Fast, secure AI inference for agents, with models and data you own ↗
Modified Source ↗
Turn your neocloud into a premium inference cloud ↗
Argyll x SambaNova: UK's First Sovereign Inference Cloud ↗
SCX.ai x SambaNova: World’s First RDU Sovereign AI Cloud ↗
Modified Source ↗
sambanova and oracle collaborate to bring high performance inference to oracle cloud infrastructure ↗
Modified Source ↗
minimax m3.1 flash now available on sambacloud ↗
Modified Source ↗
what is an ai factory ↗
Modified Source ↗
data processing agreement sambanova ↗
Modified Source ↗
Legal Agreements ↗
Modified Source ↗
sambastack on premises terms of service ↗
Modified Source ↗
introducing prompt caching for minimax m3 on sambacloud ↗
Modified Source ↗
About Us ↗
Modified Source ↗
dataflow 101 ↗
Modified Source ↗
Run sovereign AI on infrastructure you own and control ↗
Modified Source ↗
Reconfigurable Dataflow Unit (RDU) Chip ↗
Modified Source ↗
sovereign ai ↗
Modified Source ↗
Careers ↗
Modified Source ↗
Blogs ↗
Modified Source ↗
Case Studies ↗
Modified Source ↗
SambaNova in the News ↗
Modified Source ↗
Dataflow Architecture™ ↗
Modified Source ↗
Resources ↗
Modified Source ↗
Videos ↗
Modified Source ↗
White Papers ↗
Modified Source ↗
sambanova brings mohsen moazami on as vice chair of global strategy and partnerships ↗
Modified Source ↗
agentic inference needs hybrid hardware ↗
Modified Source ↗
ai efficiency survey ↗
Modified Source ↗
Build Faster Coding Agents with SambaNova’s Responses API ↗
Modified Source ↗
build self evolving agents on sambacloud with minimax 2.7 ↗
Modified Source ↗
The First Disaggregated Inference Demo for AI Agents Is Live ↗
Modified Source ↗
Gemma 4 31B Running Fastest on SambaCloud ↗
Modified Source ↗
hot chips 2026 dataflow at scale ↗
Modified Source ↗
many shot prompting a practical guide to icl ↗
Modified Source ↗
minimax m3 running fastest on sambacloud ↗
Modified Source ↗
Introducing Prompt Caching on SambaCloud: Faster, Cheaper Inference for MiniMax M2.7 ↗
Modified Source ↗
running bigger ai models more efficiently sambanova ↗
Modified Source ↗
SambaCloud Now Supports the Anthropic Messages API ↗
Modified Source ↗
sambanova and intel blog ↗
Modified Source ↗
SambaNova Joins the Genesis Mission Consortium ↗
Modified Source ↗
SemiAnalysis Benchmarks SambaRack SN50 with Fast Inference on MiniMax M2.7 ↗
Modified Source ↗
sn50 premium inference a faster roi for neoclouds ↗
Modified Source ↗
SN50 Runs the Fastest MiniMax Speeds in the World ↗
Modified Source ↗
Solving the AI Data Center Power Crisis Without New Construction ↗
Modified Source ↗
the premium inference moment is here ↗
Modified Source ↗
understanding disaggregated inference ↗
Modified Source ↗
what are ai data centers ↗
Modified Source ↗
what is ai inference ↗
Modified Source ↗
what is heterogeneous ai infrastructure ↗
Modified Source ↗
Benefits of Three-Tier Memory ↗
Modified Source ↗
Choosing the Right AI Model ↗
Modified Source ↗
sambanova hits 11b valuation ↗
Modified Source ↗
Build Lightning-Fast AI Apps with Gradio and SambaNova ↗
Modified Source ↗
Designing Effective AI Agents with CrewAI and SambaNova ↗
Modified Source ↗
Measuring Intelligence per Watt & Joule ↗
Modified Source ↗
ai chip startup sambanova raises funds at 11 billion value ↗
Modified Source ↗
axios pro rata ↗
Modified Source ↗
one to watch sambanova on premium inferencing and choosing your lane ↗
Modified Source ↗
rodrigo liang sambanova ceo a fortt knox conversation ↗
Modified Source ↗
the weeks 10 biggest funding rounds a pair of billion dollar deals for cyber and ai infrastructure lead ↗
SambaStack™ ↗
Modified Source ↗
ai is no longer about training bigger models its about inference at scale ↗
Modified Source ↗
Learn more ↗
Modified Source ↗
what is an ai chip ↗
Modified Source ↗
日本語 ↗
SambaCloud™ ↗
SambaRack™ ↗
Modified Source ↗
Developers & Enterprise ↗
Modified Source ↗
Developer showcase ↗
Modified Source ↗
Support Team ↗
Modified Source ↗
Aion Labs Uses SambaNova Cloud to Improve LLM Performance ↗
Undetectable.AI Cuts AI Detection Latency 95% with SambaCloud ↗
Modified Source ↗
Hume AI delivers speech models on SambaCloud ↗
LiquidMetal AI builds high-performance apps on SambaCloud ↗
Modified Source ↗
Maitai uses SambaCloud to deliver Inference-as-a-Service ↗
Modified Source ↗
OpenRouter Uses SambaCloud to Deliver High Speed LLM Performance ↗
Modified Source ↗
Parasail uses SambaNova Cloud to deliver extreme performance ↗
Modified Source ↗
Awards & Recognition ↗
Modified Source ↗
scx and sambanova launch australias first asic powered sovereign ai cloud ↗
Modified Source ↗
job openings ↗
Modified Source ↗
argonne national laboratory enhances ai testbed for scientific research ↗
Modified Source ↗
4X energy savings over GPUs ↗
Modified Source ↗
build real world productivity agents on sambacloud with minimax 2 5 ↗
Modified Source ↗
deepseek r1 0528 now live ↗
Modified Source ↗
deepseek v3.1 is live on sambacloud ↗
Modified Source ↗
fastest inference best models ↗
Modified Source ↗
fugaku llm in composition of experts ↗
Modified Source ↗
introducing the sambanova sdk ↗
Modified Source ↗
llm as a judge ↗
Modified Source ↗
multi agent ai workflows with crewai and sambanova ↗
Modified Source ↗
nairr pilot program ↗
Modified Source ↗
next generation large model ↗
Modified Source ↗
oak ridge national laboratory deploy sambanova suite for ai for science ↗
Modified Source ↗
only inference provider with high speed support for the largest models ↗
Modified Source ↗
responsible ai ↗
Modified Source ↗
samba coe the power of routing ml models at scale ↗
Modified Source ↗
sambalingo 15k downloads ↗
Modified Source ↗
sambanova and crewai partner to deliver agentic ai at scale on crewai amp ↗
Modified Source ↗
s barrier ↗
Modified Source ↗
sambanova vs cerebras ↗
Modified Source ↗
sambaverse discover compare evaluate ↗
Modified Source ↗
start building with lightning fast gpt oss 120b on sambacloud ↗
Modified Source ↗
start building with the fastest deepseek v3.1 terminus ↗
Modified Source ↗
supercharging ai agents with function calling on deepseek ↗
Modified Source ↗
tacc deploys sambanova suite ai inference for scientific research ↗
Modified Source ↗
the purpose built architecture ↗
Modified Source ↗
tokens per second is not all you need ↗
Modified Source ↗
transform your data privacy ↗
Modified Source ↗
bloomchat v2 ↗
Modified Source ↗
sambacoder nsql llama 2 70b model ↗
Modified Source ↗
sambalingo open source language experts ↗
Modified Source ↗
日本語 ↗
Modified Source ↗
models 101 ↗
Modified Source ↗
9 predictions for ai in 2025 ↗
Modified Source ↗
sn40l chip best inference solution ↗
Modified Source ↗
ultra fast recurrent neural networks with sambanovas reconfigurable dataflow architecture ↗
Modified Source ↗
日本語 ↗
Modified Source ↗
hume ai delivers speech models on sambacloud ↗
Modified Source ↗
accelerating scientific applications with sambanova reconfigurable dataflow architecture ↗
Modified Source ↗
ultra fast recurrent neural networks with sambanovas reconfigurable dataflow architecture ↗
Modified Source ↗
SambaNova Completes First Close of $1B Financing at $11B Valuation ↗
Modified Source ↗
intel backed ai chip startup sambanova breathes new life into aging nvidia gpus in latest benchmarks ↗
Modified Source ↗
awards ↗
Modified Source ↗
ai chip maker sambanova raises 1b at 11b valuation 5 months after last mega round ↗
Modified Source ↗
ai chip startup sambanova valued at 11 billion in 1 billion funding round ↗
Modified Source ↗
inference chip startup sambanova valued at 11b in 1b funding round ↗
Modified Source ↗
rodrigo liang sambanova systems raise summit 2026 ↗
Modified Source ↗
sambanova ceo strongly considering ipo likely in u.s ↗
Modified Source ↗
sambanova close 1b in financing at 11b valuation ↗
Modified Source ↗
sambanova hits 11 billion valuation as investors back nvidia chip challengers ↗
Modified Source ↗
sambanova raises 1b signs jpmorganchase as a customer ↗
Modified Source ↗
sambanova the underdog in the semiconductor industry that dreams of competing with nvidia ↗
Modified Source ↗
this billion dollar startup is challenging nvidias grip on ai computing ↗
Modified Source ↗
ai chip maker sambanova raises 1b at 11b valuation 5 months after last mega round ↗
Modified Source ↗
ai chip startup sambanova valued at 11 billion in 1 billion funding round ↗
Modified Source ↗
inference chip startup sambanova valued at 11b in 1b funding round ↗
Modified Source ↗
intel backed ai chip startup sambanova breathes new life into aging nvidia gpus in latest benchmarks ↗
Modified Source ↗
rodrigo liang sambanova systems raise summit 2026 ↗
Modified Source ↗
sambanova ceo strongly considering ipo likely in u.s ↗
Modified Source ↗
sambanova close 1b in financing at 11b valuation ↗
Modified Source ↗
sambanova hits 11 billion valuation as investors back nvidia chip challengers ↗
Modified Source ↗
sambanova raises 1b signs jpmorganchase as a customer ↗
Modified Source ↗
sambanova the underdog in the semiconductor industry that dreams of competing with nvidia ↗
Modified Source ↗
this billion dollar startup is challenging nvidias grip on ai computing ↗
Modified Source ↗
accelerated computing with a reconfigurable dataflow architecture ↗
Modified Source ↗
ai is changing everything ↗
Modified Source ↗
build or buy ↗
Modified Source ↗
Composition of Experts: Next Wave of AI Innovation ↗
Modified Source ↗
AI Model Ownership: 3 Critical Considerations ↗
Modified Source ↗
silicon steel ↗
Modified Source ↗
sambanova introduces new ai accelerator partners with intel to deploy xeon cpus for inferencing and agentic workloads sambanova claims sn50 chip is three ti 1781255323204 ↗
Modified Source ↗
getting started with sambacloud ↗
Modified Source ↗
the open source model ecosystem ↗
Modified Source ↗
top use cases for fast ai ↗
Modified Source ↗
welcome to samba academy ↗
Modified Source ↗
SambaAcademy ↗
Modified Source ↗
sambanova ceo on ipo prospects were excited for what the next 12 months will bring newsroom ↗
Modified Source ↗
1 trillion parameter generative ai model for enterprises ↗
Modified Source ↗
amazing 1 trillion parameter large scale language model ↗
Modified Source ↗
analog devices adopts sambanova suite ↗
Modified Source ↗
hpc wire japan ↗
Modified Source ↗
makers conquer generative ai bottlenecks ↗
Modified Source ↗
post gpu weapon target nvidia bottleneck ↗
Modified Source ↗
precision accuracy scale and experience all matter with ai ↗
Modified Source ↗
reducing the cost of inference by a tenth ↗
Modified Source ↗
riken on fugaku adopts sambanova ↗
Modified Source ↗
rikens choice for sambanova ↗
Modified Source ↗
sambanova 28 times more efficient than nvidia ↗
Modified Source ↗
softbank selects sambanova as platform for generative ai development ↗
Modified Source ↗
tokyo office targeting government and financial sector ↗
Modified Source ↗
intel strikes deal witha chip start up its c.e.o. invested in ↗
Modified Source ↗
argyll and sambanova launch sovereign ai cloud in the uk ↗
Modified Source ↗
forbes unveils 2026 ai 50 marking shift from ai dominance to ai independence ↗
Modified Source ↗
how sambanova is challenging nvidia with high performance inferencing technology ↗
Modified Source ↗
intel and sambanova team up on heterogeneous ai inference platform different hardware platforms different workloads ↗
Modified Source ↗
intel sambanova bet on split inference as agentic ai strains gpus ↗
Modified Source ↗
sambanova and intel expand partnership with inference and architecture to support agentic ai workloads ↗
Modified Source ↗
sambanova ceo on ipo prospects were excited for what the next 12 months will bring ↗
Modified Source ↗
sambanova ceo on making ai more affordable ↗
Modified Source ↗
sambanova challenges cerebras strategy ↗
Modified Source ↗
sambanova teams up with intel on disaggregated inference ↗
Modified Source ↗
sambanova unveils sn50 ai chip intel partnership and 350m fundraise 1 ↗
Modified Source ↗
the ai industry spent years chasing bigger models. now its chasing efficiency ↗
Modified Source ↗
the cpu is the systems executive layer intel joins sambanova as both face existential threat from nvidias groq powered inference ↗
Modified Source ↗
sambanova names engineering and finance leaders to accelerate growth ↗
Modified Source ↗
modern ai infrastructure demands model bundling ↗
Modified Source ↗
Solving the Infrastructure Crisis for AI Inference with Dataflow ↗
Modified Source ↗
careers ↗
Modified Source ↗
sambamanaged ↗
Modified Source ↗
日本語 ↗
Modified Source ↗
developers enterprise ↗
Modified Source ↗
government public sector ↗
Modified Source ↗
support ↗
Modified Source ↗
smarter machines risk creaking dumber humans ↗
Modified Source ↗
the impact of ai on the digital future of healthcare and life sciences ↗
Modified Source ↗
platform ↗
Modified Source ↗
日本語 ↗
Modified Source ↗
introducing bloomchat 176b the multilingual chat based llm ↗
Modified Source ↗
ai computer vision ↗
Modified Source ↗
SambaNova & TEPCO Systems Partner to Deliver Energy-Efficient AI Infrastructure to Japan’s Power Sector ↗
Modified Source ↗
cloud end user license agreement ↗
Modified Source ↗
Privacy Policy ↗
Modified Source ↗
product safety and compliance statements ↗
Modified Source ↗
sambastack hosted terms of service ↗
Modified Source ↗
terms and conditions ↗
Modified Source ↗
sambanova announces collaboration with intel on ai solution ↗
Modified Source ↗
the openclaw x sambanova playbook for agentic workflows ↗
Modified Source ↗
meta amd deal fuels ai spending surge open interest 2 24 2026 ↗
Modified Source ↗
how one ai company is helping businesses navigate trumps new tariff chaos following the supreme court ruling ↗
Modified Source ↗
intel backed sambanova raises cash touts softbank chip contract ↗
Modified Source ↗
intel partners with ai chip startup sambanova after acquisition talks reportedly failed ↗
Modified Source ↗
sambanova raises 350m as more upstarts take on nvidias dominance ↗
Modified Source ↗
sambanova raises 350m with intel backing ↗
Modified Source ↗
sambanova steps up its challenge to nvidia with new chip 350m funding and a powerful ally in intel ↗
Modified Source ↗
sambanova unveils sn50 ai chip intel partnership and 350m fundraise ↗
Modified Source ↗
sambanova unveils fastest chip for agentic ai collaborates with intel and raises 350m ↗
Modified Source ↗
research finds ais energy use is driving concern ↗
Modified Source ↗
sambanova unveils fastest chip for agentic ai collaborates with intel and raises 350m ↗
Modified Source ↗
software end user license agreement ↗
Modified Source ↗
accelerating coding with sambanova cloud ↗
Modified Source ↗
are llms truly solving software problems ↗
Modified Source ↗
building your first agentic ai app with sambanova cloud and n8n ↗
Modified Source ↗
Inference Speed or Throughput? With RDUs, You Don't Have to Choose ↗
Modified Source ↗
Agentic Caching ↗
Modified Source ↗
sambanova cloud launches the fastest deepseek r1 671b ↗
Modified Source ↗
Learn More ↗
Modified Source ↗
sambanova vs groq ↗
Modified Source ↗
understanding mcp ↗
Modified Source ↗
sovereign ai national autonomy in the ai era ↗
Modified Source ↗
Rodrigo Liang Talks AI with The Information ↗
Modified Source ↗
Connect with our AI experts ↗
Modified Source ↗
ai for science ↗
Modified Source ↗
solving the ai scale dilemma when the ai innovation imperative meets barriers of scale skill and compute 2 ↗
Modified Source ↗
Subscribe ↗
Modified Source ↗
same model three platforms what function calling benchmarks reveal ↗
Modified Source ↗
ai trends 2026 insights ↗
Modified Source ↗
alibi interpolation vs extrapolation ↗
Modified Source ↗
can llama 405b outperform gpt4 ↗
Modified Source ↗
domain adapted asr ↗
Modified Source ↗
generative ai terms ↗
Modified Source ↗
infercom qna ↗
Modified Source ↗
scx qna ↗
Modified Source ↗
achieving gpt 175b level accuracy with a 10x more efficient model ↗
Modified Source ↗
correcting common ai benchmarking errors ai starter kits ↗
Modified Source ↗
dataflow architecture leads to a performance breakthrough on gnn fused kernels ↗
Modified Source ↗
does reduced precision hurt ↗
Modified Source ↗
fault management and rda systems part 1 ↗
Modified Source ↗
from insight to action with sambanova agents ↗
Modified Source ↗
introducing whisper large v3 ↗
Modified Source ↗
qwen 2.5 32b coder available on sambanova cloud ↗
Modified Source ↗
qwen3 is here ↗
Modified Source ↗
redefining ai infrastructure in a power constrained world ↗
Modified Source ↗
sambanova 2.0 build with relentless intelligence ↗
Modified Source ↗
sambanova cloud delivers fast inference ↗
Modified Source ↗
sambanova cloud tulu 3 405b a new model better than deepseek v3 ↗
Modified Source ↗
series d ↗
Modified Source ↗
ai chip startup sambanova snags 56 million in funding ↗
Modified Source ↗
intel capital bets big 117m investment in 14 tech startups ↗
Modified Source ↗
sambanova claims ai performance rivaling nvidia unveils as a service offering ↗
Modified Source ↗
sambanova heads to unicorn status raises 150 million ↗
Modified Source ↗
ai leadership survey exposes readiness gap most enterprises are unprepared for ai power demand ↗
Modified Source ↗
aicadium and sambanova join forces to bring innovative end to end hardware and software ai solution to singapore ↗
Modified Source ↗
analog devices deploys sambanova suite ↗
Modified Source ↗
argonne national laboratory deploys a new sambanova inference optimized cluster to support ai driven science ↗
Modified Source ↗
argyll and sambanova partner to deliver the uks first renewable powered sovereign ai cloud ↗
Modified Source ↗
cyber bytes foundation hosts innovation labs grand opening event with cutting edge technology organizations including sambanova systems ↗
Modified Source ↗
darpa leader joins sambanova advisory board ↗
Modified Source ↗
fastest deepseek r1 671b with highest efficiency ↗
Modified Source ↗
fugaku llm is now a part of samba 1 ↗
Modified Source ↗
high speed ai web3 world ↗
Modified Source ↗
highest training performance for gpt now accessible as a service to enterprises by sambanova systems ↗
Modified Source ↗
japans commitment to ai spurs further international expansion by sambanova systems to meet the countrys technology priorities ↗
Modified Source ↗
lip bu tan executive chairman ↗
Modified Source ↗
los alamos national laboratory select sambanova suite to facilitate its generative ai and llm capabilities ↗
Modified Source ↗
new gpt ai powered large language model for banking increases financial services institutions competitiveness and enables accelerated digital transformation ↗
Modified Source ↗
new research shows that over half of banking leaders expect to see significant business impact from ai ↗
Modified Source ↗
new research shows that uk enterprise ai teams are under resourced 80 of it leaders report it ↗
Modified Source ↗
new study reveals more than 78 of companies cite ai as a key revenue driver in 2022 ↗
Modified Source ↗
oak ridge national laboratory expands research in secure and energy efficient ai ↗
Modified Source ↗
organizations gain access to the most advanced ai solutions with sambanova and orock technologies offering highest performance models in a secure cloud ↗
Modified Source ↗
otp bank selects sambanova systems to build europes fastest ai supercomputer ↗
Modified Source ↗
over half of global business leaders believe investing in ai will give them a competitive advantage ↗
Modified Source ↗
ovhcloud selects sambanova to power flagship ai endpoints inferencing service ↗
Modified Source ↗
peter buckingham joins sambanova as vp of software engineering ↗
Modified Source ↗
sambanova accelerates ai for banking and the public sector with a world record performance system new partnerships and international expansion in 2022 ↗
Modified Source ↗
sambanova accelerates seismic analysis enabling faster resource discovery for oil and gas companies ↗
Modified Source ↗
sambanova and canvass partner ↗
Modified Source ↗
sambanova and hume ai unleash lightning fast multilingual speech language model to redefine conversational ai for global enterprises ↗
Modified Source ↗
sambanova and lawrence livermore national laboratory scale up collaboration to accelerate ai for science ↗
Modified Source ↗
sambanova announces elevaite ↗
Modified Source ↗
sambanova announces generative ai program for startups ↗
Modified Source ↗
sambanova announces next generation datascale system setting a world record for time to train performance ↗
Modified Source ↗
sambanova boosts leadership team with duo of industry veterans ↗
Modified Source ↗
sambanova continues executive leadership team expansion with the addition of poonacha kongetira as vp of hardware ↗
Modified Source ↗
sambanova datascale selected for softbank corp generative ai computing platform ↗
Modified Source ↗
sambanova deepens technical talent and executive leadership team with addition of prabhdeep singh as vp of software product ↗
Modified Source ↗
sambanova delivers generative ai capabilities to the enterprise ↗
Modified Source ↗
sambanova delivers next generation datascale system to argonne national laboratory ↗
Modified Source ↗
sambanova expands deployment with softbank corp fast ai inference apac ↗
Modified Source ↗
SambaNova Launches First Turnkey AI Inference Solution for Data Centers, Deployable in 90 Days ↗
Modified Source ↗
SambaNova Launches its AI Platform in AWS Marketplace ↗
Modified Source ↗
sambanova named 4 on fast companys most innovative companies of 2025 list ↗
Modified Source ↗
sambanova powers eus first sovereign ai inference service with infercom ↗
Modified Source ↗
sambanova powers the ai backbone for three sovereign ai providers across australia europe and the u.k ↗
Modified Source ↗
sambanova scorches nvidia in new speed test ↗
Modified Source ↗
sambanova systems and scaleworx enter historic partnership to drive artificial intelligence adoption and applications in asia ↗
Modified Source ↗
sambanova systems announces 150m series b from intel capital and gv to advance its breakthrough ai platform ↗
Modified Source ↗
sambanova systems announces 250 million series c as it continues to set a new course for the future of enterprise computing ↗
Modified Source ↗
sambanova systems announces international expansion in emea ↗
Modified Source ↗
sambanova systems appoints dr. edward frank to its board of advisors ↗
Modified Source ↗
sambanova systems appoints jonathan chang as new general counsel ↗
Modified Source ↗
sambanova systems appoints two new board members to help drive long term growth as traction for companys industry redefining technology accelerates ↗
Modified Source ↗
sambanova systems as part of new industry and research consortium to establish standard benchmark suite for machine learning ↗
Modified Source ↗
sambanova systems continues to attract top industry talent with the addition of matt taylor as vp of strategic sales and partnerships ↗
Modified Source ↗
sambanova systems emerges from stealth and secures 56 million in series a funding led by walden international and gv ↗
Modified Source ↗
sambanova systems expands bill moores key strategy role ↗
Modified Source ↗
sambanova systems expands leadership team by appointing marshall choy vp of product ↗
Modified Source ↗
sambanova systems extends participation in academic research ↗
Modified Source ↗
sambanova systems named 2019 startup to watch by global semiconductor alliance ↗
Modified Source ↗
sambanova systems named a 2021 gartner cool vendor in ai semiconductors ↗
Modified Source ↗
sambanova systems names eli collins to key strategy role ↗
Modified Source ↗
sambanova systems opens tokyo technology center ↗
Modified Source ↗
sambanova systems to deliver sambanova datascale to riken ↗
Modified Source ↗
sambanova systems to showcase worlds most advanced software hardware and services for ai at gitex 2021 ↗
Modified Source ↗
sambanova systems ushers in new era of computing with availability of sambanova datascale built for ai ↗
Modified Source ↗
sambanova systems wins best innovation in ai hardware 2020 aiconics award ↗
Modified Source ↗
sambanova unveils new chip the sn40l ↗
Modified Source ↗
sambanovaas dataflow as a servicea recognized as the best big data deep learning ai solution by the 2022 tech ascension awards ↗
Modified Source ↗
sambaverse empowering developers to compare the speed and accuracy of open source llms ↗
Modified Source ↗
scbx scb 10x sambanova expand ai models ↗
Modified Source ↗
secure one trillion parameter generative ai model for the enterprise ↗
Modified Source ↗
series d ↗
Modified Source ↗
systems architecture pioneer and co founder of sambanova systems to speak at the ai hardware summit ↗
Modified Source ↗
tacc selects sambanova ai to accelerate scientific research ↗
Modified Source ↗
technology industry veteran geoffrey ribar named sambanova systems interim chief financial officer ↗
Modified Source ↗
worlds fastest ai platform ↗
Modified Source ↗
worlds first enterprise grade gpt ai powered language model introduced by sambanova systems ↗
Modified Source ↗
worlds most advanced ai solutions platform appoints first chief marketing officer to accelerate go to market engagements and global presence ↗
Modified Source ↗
argyll qna ↗
Modified Source ↗
full stack approach to ai succeeding ↗
Modified Source ↗
speed record on llama 3.1 405b ↗
Modified Source ↗
subgoalx formal theorem proving ↗
Modified Source ↗
test time compute available with qwen qwq 32b preview ↗
Modified Source ↗
Agentic AI Is Rewriting the Rules of Business ↗
Modified Source ↗
2022 the defining year for ai breakthroughs at scale ↗
Modified Source ↗
2024 predictions ↗
Modified Source ↗
3 keys to building a successful ai project team ↗
Modified Source ↗
accenture and sambanova delivering generative ai to the enterprise ↗
Modified Source ↗
ai innovation in the foundation model era ↗
Modified Source ↗
announcing sambanova gpt banking ↗
Modified Source ↗
benchmarking samba 1 ↗
Modified Source ↗
conversation with ceo snorkel ↗
Modified Source ↗
conversation with cto c3 ↗
Modified Source ↗
cost effective generative ai subscription ↗
Modified Source ↗
enabling open source llms to become effective tool manipulators ↗
Modified Source ↗
explaining explainability in ai ↗
Modified Source ↗
fault management and rda systems part 2 ↗
Modified Source ↗
foundation models and the new era of ai ↗
Modified Source ↗
how ai solutions meet complex and costly compliance challenges in financial services ↗
Modified Source ↗
importance open source models enterprise ↗
Modified Source ↗
introducing text embedding model support in sambastudio elevating information retrieval and augmenting large language models ↗
Modified Source ↗
let the data flow ↗
Modified Source ↗
los alamos national laboratory expands partnership with sambanova ↗
Modified Source ↗
otp bank selects sambanova systems to build europes fastest ai supercomputer ↗
Modified Source ↗
rags ↗
Modified Source ↗
samba 1 composition of experts mode ↗
Modified Source ↗
samba coe v01 composition of experts ↗
Modified Source ↗
start spreading the news new york new york ↗
Modified Source ↗
ml systems for processing sensor data ↗
Modified Source ↗
the idc perspective on the business value of natural language processing ↗
Modified Source ↗
the insurmountable challenge of building ai at scale ↗
Modified Source ↗
the race to ai value 3 themes from new ai ml and deep learning research report ↗
Modified Source ↗
three takeaways from sambanovaas conversation on generative ai with vipul ved prakash co founder and ceo of together ↗
Modified Source ↗
training long sequence size models on sambanova ↗
Modified Source ↗
world record large language models training performance sambanova dataflow as a service gpt ↗
Modified Source ↗
events old ↗
Modified Source ↗
The Power of Detailed Prompts in AI ↗
Modified Source ↗
ace open sourced on github ↗
Modified Source ↗
creating valuable ai ↗
Modified Source ↗
deepseek v3 0324 fastest inference in world ↗
Modified Source ↗
generative ai model ownership ↗
Modified Source ↗
gradio makes building apps on sambanova cloud super easy ↗
Modified Source ↗
hugging face faster to review papers with sambanova ↗
Modified Source ↗
hugging face partners with sambanova to supercharge its inference api capabilities ↗
Modified Source ↗
introducing sambamanaged a turnkey path to ai for data centers ↗
Modified Source ↗
llm judge for multilingual document question answering ↗
Modified Source ↗
meta llama 3.3 70b now available today for developers and enterprises ↗
Modified Source ↗
outperforming gpt 4o with llama 3 8b fine tuning rag ↗
Modified Source ↗
predictions for llama 3 405b ↗
Modified Source ↗
sambanova cloud developer tier is live ↗
Modified Source ↗
sambanova named to fortune future 50 list for second consecutive year ↗
Modified Source ↗
sambanova partners with meta to deliver lightning fast inference on llama 4 ↗
Modified Source ↗
startup accelerator helping ai innovators realize their vision ↗
Modified Source ↗
unlock enterprise grade security with lattice ai and sambanova ↗
Modified Source ↗
using mixed precision on rdus ↗
Modified Source ↗
zilliz powering ai rag applications with vector embeddings ↗
Modified Source ↗
日本語 ↗
Modified Source ↗
日本語 ↗
Modified Source ↗
日本語 ↗
Modified Source ↗
78 of uk financial services leaders struggling to keep pace with ai ↗
Modified Source ↗
80 uk it leaders struggle to keep up with ai technology amidst ongoing talent shortage ↗
Modified Source ↗
a powerful ai platform sambanova suite ↗
Modified Source ↗
accenture deploys sambanova system for generative ai ↗
Modified Source ↗
ai chip startups pull in funding as they navigate supply constraints ↗
Modified Source ↗
ai deployment data strategy security and privacy ↗
Modified Source ↗
argonne national laboratory deploys sambanova datascale system ↗
Modified Source ↗
dcd magazine issue 48 what generative ai means for data centers supercomputers the cloud ↗
Modified Source ↗
dcd magazine out soon generative ai and the future of data centers ↗
Modified Source ↗
decoding the ai stack and how to succeed in the ai value chain ↗
Modified Source ↗
elastic enters the generative ai space with new enterprise search platform ↗
Modified Source ↗
enterprise startups race to cash in on chatgpt mania ↗
Modified Source ↗
generative ai the futur of data centers part v the chipse ↗
Modified Source ↗
generative ai the future of data centers part ii the players ↗
Modified Source ↗
how a disney and pg director found her own direction ↗
Modified Source ↗
how the public clouds are innovating on ai ↗
Modified Source ↗
hpc roundup frontier retains first place as worlds fastest supercomputer on top500 list ↗
Modified Source ↗
llama 3.1 a boon for enterprises and a bane for other llm vendors ↗
Modified Source ↗
microsoft and openai enter third phase of ai acceleration partnership ↗
Modified Source ↗
microsoft confirms multibillion dollar openai investment ↗
Modified Source ↗
next big things in tech 2021 ↗
Modified Source ↗
sambanova launches ai inference cloud ↗
Modified Source ↗
sambanova system added to fugaku supercomputer to boost ai performance ↗
Modified Source ↗
smart machines the 14 next big things from instant rockets to smart tractors ↗
Modified Source ↗
the biggest tech trends of 2023 according to over 40 experts ↗
Modified Source ↗
ai energy efficiency monitoring ranks low among enterprise users survey by inference hardware specialists finds ↗
Modified Source ↗
bryan johnsons dont die movement softbanks ai gamble perplexitys browser bids aug 14 2025 ↗
Modified Source ↗
deepseek just flipped the script in favour of open source ai models sambanova ceo ↗
Modified Source ↗
enterprises in for a shock when they realize power and cooling demands of ai ↗
Modified Source ↗
europes ai future hinges on one thing energy sambanova ceo ↗
Modified Source ↗
forbes 2025 ai 50 list top artificial intelligence companies ranked ↗
Modified Source ↗
fortune future 50 2025 fortune ↗
Modified Source ↗
improving on a 30 year old hardware architecture ↗
Modified Source ↗
infrastructure investment needed for ai to scale sambanova systems ceo liang says ↗
Modified Source ↗
preparing for tomorrows agentic workforce ↗
Modified Source ↗
sambanova ceo ai infrastructure incredibly important for governments live interview on cnbc ↗
Modified Source ↗
sambanova debuts framework for lower cost open source deep research agents ↗
Modified Source ↗
third party ai tools are muddying sustainability metrics ↗
Modified Source ↗
rodrigo liang on agentic ai ↗
Modified Source ↗
sambanova powers the ai backbone for three sovereign ai providers across australia europe and the u.k ↗
Modified Source ↗
ai will kill these jobs but create new ones too ↗
Modified Source ↗
blackrock backed sambanova launches worlds fastest ai inference service ↗
Modified Source ↗
how to train your chatbot through prompt engineering ↗
Modified Source ↗
microsoft makes multi billion dollar investment in openai as partnership enters third phase ↗
Modified Source ↗
new study reveals more than 78 of companies cite ai as a key revenue driver in 2023 ↗
Modified Source ↗
openai unveils gpt 4 a new foundation for chatgpt ↗
Modified Source ↗
sambanova ceo were built for large ↗
Modified Source ↗
sambanova introduces new chip designed for 5 trillion parameter models ↗
Modified Source ↗
sambanova new ai chip runs 5 trillion parameter models ↗
Modified Source ↗
scaling ai without breaking the grid the path to sustainable innovation ↗
Modified Source ↗
uk enterprise ai teams are under resourced ↗
Modified Source ↗
uk enterprise ai teams are under resourced 1 ↗
Modified Source ↗
first with trillion parameter genai model ↗
Modified Source ↗
iphone of ai ↗
Modified Source ↗
meta turns to lg to hit back at apple vision pro and other technology news today ↗
Modified Source ↗
samba 1 with ian king on sky business live ↗
Modified Source ↗
the worlds fastest ai platform ↗
Modified Source ↗
sambanova chip runs models 5 trillion parameters ↗
Modified Source ↗
sambanovas new chip means gpts for everyone ↗
Modified Source ↗
sambanovas new chip runs ai models to 5 trillion parameters ↗
Modified Source ↗
sambanova and hume ai unleash lightning fast multilingual speech language model to redefine conversational ai for global enterprises ↗
Modified Source ↗
sambanova challenges openai o1 model ↗
Modified Source ↗
composition of experts ↗
Modified Source ↗
sambanova launches its ai platform in aws marketplace ↗
Modified Source ↗
sambanova launches first turnkey ai inference solution for data centers deployable in 90 days clone ↗
Modified Source ↗
power and energy will be the ai bottleneck ↗
Modified Source ↗
thank you ↗
Modified Source ↗
nairr pilot ↗
Modified Source ↗
Announcements & News ↗
Modified Source ↗
thank you ↗
Modified Source ↗
sambanova expands deployment with softbank corp fast ai inference apac ↗
Modified Source ↗
fastest deepseek r1 671b with highest efficiency ↗
Modified Source ↗
stc to introduce ksas inferencing as a service cloud worlds largest open source frontier model ↗
Modified Source ↗
DeepSeek just flipped the script in favor of open source AI models: Rodrigo Liang, SambaNova ↗
Modified Source ↗
cnbc sanctuary davos ↗
Modified Source ↗
CNBC Sanctuary: Can Nvidia's AI dominance in chips be challenged? ↗
Modified Source ↗
ai leadership survey exposes readiness gap most enterprises are unprepared for ai power demand ↗
Modified Source ↗
fugaku supercomputer powers local ai model training ↗
Modified Source ↗
rodrigo liang on agentic ai ↗
Modified Source ↗
sambanova integrates fugaku llm into its advanced samba 1 coe tech ↗
Modified Source ↗
shift from simple chatbots to more complex ai systems ↗
Modified Source ↗
the race is on to control the global supply chain for ai chips ↗
Modified Source ↗
the worlds fastest ai platform revolutionizing developer access to llama models ↗
Modified Source ↗
Argonne National Laboratory, Venkatram Vishwanath ↗
Modified Source ↗
Oak Ridge National Laboratory, Prasanna Balaprakash ↗
Modified Source ↗
Texas Advanced Computing Center, Dan Stanzione ↗
Modified Source ↗
thank you ↗
Modified Source ↗
Argonne National Laboratory, Rick Stevens ↗
Modified Source ↗
Kunle Olukotun interview on CNBC at Slush 2024 ↗
Modified Source ↗
high cost gpus not fit for next phase of ai ↗
Modified Source ↗
large enterprises embrace hybrid compute to retain control of their own intelligence ↗
Modified Source ↗
argonne national laboratory deploys a new sambanova inference optimized cluster to support ai driven science ↗
Modified Source ↗
oak ridge national laboratory expands research in secure and energy efficient ai ↗
Modified Source ↗
tacc selects sambanova ai to accelerate scientific research ↗
Modified Source ↗
hugging face sambanova create one click chatbot integration ↗
Modified Source ↗
can nvidia be disrupted ↗
Modified Source ↗
sambanova hugging face ai chatbot deployment one click integration ↗
Modified Source ↗
what could slow nvidia down ↗
Modified Source ↗
ai chip startups sell to mideast ↗
Modified Source ↗
challengers are coming for nvidia crown ↗
Modified Source ↗
enhances modular ai deployment through composition of experts on the sambanova sn40l platform ↗
Modified Source ↗
fastest ai platform with llama 3.1 405b at 132 tokens per second ↗
Modified Source ↗
nvidia days of dominance in ai could be numbered ↗
Modified Source ↗
sambanova gradio are making high speed ai accessible ↗
Modified Source ↗
small ai chip makers eye gains in inference workloads ↗
Modified Source ↗
watching us chip exports closely ↗
Modified Source ↗
ai inference compute in the datacenter ↗
Modified Source ↗
ai infrastructure silicon valley executive series ↗
Modified Source ↗
putting the brakes on the ai hype ↗
Modified Source ↗
revolutionizing developer access to llama models ↗
Modified Source ↗
sambanova launches ai inference cloud platform ↗
Modified Source ↗
sambanova makes llama gallop in inference cloud debut ↗
Modified Source ↗
sambanova systems intros ai inference platform ↗
Modified Source ↗
token wars heats up ↗
Modified Source ↗
coolest technology award venturebeat transform 2024 ↗
Modified Source ↗
dataflow architecture transforms high performance ai chips for enterprises ↗
Modified Source ↗
new llama model could be a game changer ↗
Modified Source ↗
datascale sn30 ↗
Modified Source ↗
lawrence livermore national laboratory accelerate ai for science ↗
Modified Source ↗
worlds fastest ai platform ↗
Modified Source ↗
enterprise ai platform sambanova suite ↗
Modified Source ↗
thank you ↗
Modified Source ↗
fast api ↗
Modified Source ↗
gen ai public sector government ↗
Modified Source ↗
api thank you ↗
Modified Source ↗
abc genai conference ↗
Modified Source ↗
abc gen ai conference ↗
Modified Source ↗
sambanova scorches nvidia in new speed test ↗
Modified Source ↗
sambanova breaks llama 3 speed record ↗
Modified Source ↗
lip bu tan executive chairman ↗
Modified Source ↗
five global ai hardware startups ↗
Modified Source ↗
the 10 coolest ai chip startups of 2020 ↗
Modified Source ↗
fugaku llm is now a part of samba 1 ↗
Modified Source ↗
sambaverse empowering developers to compare the speed and accuracy of open source llms ↗
Modified Source ↗
enterprise ai company ↗
Modified Source ↗
investors funding ↗
Modified Source ↗
custom generative ai models ↗
Modified Source ↗
sambanova suite ai demos ↗
Modified Source ↗
machine learning method to adapt pretrained llms to new languages ↗
Modified Source ↗
most enterprises just starting with ai ↗
Modified Source ↗
samba 1 on street signs cnbc ↗
Modified Source ↗
sambanova systems sets new ai efficiency record with samba coe v02 ↗
Modified Source ↗
sambanova trains trillion parameter model to take on gpt 4 ↗
Modified Source ↗
a look at sambanovas open source ai strategy ↗
Modified Source ↗
samba coe v02 already beats databricks dbrx ↗
Modified Source ↗
cnbc exclusive ↗
Modified Source ↗
models ↗
Modified Source ↗
secure one trillion parameter generative ai model for the enterprise ↗
Modified Source ↗
sambanova debuts composition of experts ai model with 1t parameters ↗
Modified Source ↗
sambanova pits llm collective against monolithic ai models ↗
Modified Source ↗
sambanova debuts 1 trillion parameter composition of experts model for enterprise gen ai ↗
Modified Source ↗
sambanova now offers a bundle of generative ai models ↗
Modified Source ↗
sambanova systems intros samba 1 generative ai model ↗
Modified Source ↗
sambanova unveils samba 1 a 1 trillion parameter generative ai for enhanced enterprise privacy ↗
Modified Source ↗
registration thank you new ↗
Modified Source ↗
registration thank you new ↗
Modified Source ↗
support portal ↗
Modified Source ↗
aicadium and sambanova join forces to bring innovative end to end hardware and software ai solution to singapore ↗
Modified Source ↗
アナログデバイセズ全社規模で画期的な生成ai ↗
Modified Source ↗
ascend clinical chooses category leaders delorean ai and sambanova to advance renal care with ai ↗
Modified Source ↗
sambanova accelerates seismic analysis enabling faster resource discovery for oil and gas companies ↗
Modified Source ↗
sambanova and lawrence livermore national laboratory scale up collaboration to accelerate ai for science ↗
Modified Source ↗
sambanova announces generative ai program for startups ↗
Modified Source ↗
sambanova continues executive leadership team expansion with the addition of poonacha kongetira as vp of hardware ↗
Modified Source ↗
sambanova datascaleがソフトバンクの生成ai開発向け計算基盤に ↗
Modified Source ↗
sambanova delivers generative ai capabilities to the enterprise ↗
Modified Source ↗
sambanova delivers next generation datascale system to argonne national laboratory ↗
Modified Source ↗
sambanova systems and scaleworx enter historic partnership to drive artificial intelligence adoption and applications in asia ↗
Modified Source ↗
sambanova systems sponsors miru for the first time and sets new standard for true resolution image recognition ↗
Modified Source ↗
sambanova unveils new chip the sn40l ↗
Modified Source ↗
worlds first enterprise grade gpt ai powered language model introduced by sambanova systems ↗
Modified Source ↗
japans commitment to ai spurs further international expansion by sambanova systems to meet the countrys technology priorities ↗
Modified Source ↗
new gpt ai powered large language model for banking increases financial services institutions competitiveness and enables accelerated digital transformation ↗
Modified Source ↗
sambanova systems opens tokyo technology center ↗
Modified Source ↗
sambanova systems to deliver sambanova datascale to riken ↗
Modified Source ↗
composition of experts ↗
Modified Source ↗
contact alt ↗
Modified Source ↗
thank you financial services ↗
Modified Source ↗
thankyou ↗
Modified Source ↗
solutions ↗
Modified Source ↗
podcasts ↗
Modified Source ↗
blog ↗
Modified Source ↗
news ↗
Modified Source ↗
press ↗
Modified Source ↗
los alamos national laboratory select sambanova suite to facilitate its generative ai and llm capabilities ↗
Modified Source ↗
sambanova announces next generation datascale system setting a world record for time to train performance ↗
Modified Source ↗
2024 genai predictions part one ↗
Modified Source ↗
big data industry predictions for 2024 ↗
Modified Source ↗
sambanova unveils new ai chip to power full stack ai platform ↗
Modified Source ↗
ai summit 2021 ↗
Modified Source ↗
department of defense intelligence information system dodiis worldwide conference ↗
Modified Source ↗
himss ↗
Modified Source ↗
metas llama 2 ai model coming to qualcomm powered smartphones as part of significant shift to open source 1 ↗
Modified Source ↗
openai expands chatgpt custom personality feature ↗
Modified Source ↗
companies tie ai success to cost savings revenue growth report ↗
Modified Source ↗
the ai team in search of silicon valleys next great chip company ↗
Modified Source ↗
the cutting edge computer architecture thats changing the ai game vb live ↗
Modified Source ↗
the future of llms compute democratization and open source models ↗
Modified Source ↗
the insidebigdata impact 50 list for q3 2023 ↗
Modified Source ↗
the multicore era is over we need a new architecture for ai ↗
Modified Source ↗
the music stopped 6 founders share how they survived this years bursting vc funding bubble customers unwilling to spend and a graveyard of fallen startup peers ↗
Modified Source ↗
ml landscape identify and overcome barriers to scale ↗
Modified Source ↗
top 11 new us unicorns by post money valuation ↗
Modified Source ↗
top 3 challenges in ai faced by uk financial services firms ↗
Modified Source ↗
training llms on private data for higher accuracy ↗
Modified Source ↗
u.s. argonne national lab scales up startup sambanovas latest ai system ↗
Modified Source ↗
upstart claims its chips beat nvidias a100 on ai oomph ↗
Modified Source ↗
us news and world report ai chip maker sambanova raises 676 million valued at over 5 billion ↗
Modified Source ↗
venturebeat sambanova raises 676m to mass produce ai training and inference chips ↗
Modified Source ↗
what netflixs recommendation systems can teach us about the computing challenges of the near future ↗
Modified Source ↗
who should run vmware sizing up the likely candidates ↗
Modified Source ↗
why ai leaders need a backbone of large language models ↗
SambaNova Systems releases enterprise-grade GPT AI-powered language model ↗
Modified Source ↗
2021 an incredible year of ai in review ↗
Modified Source ↗
2022 technology predictions for ai in the enterprise ↗
Modified Source ↗
78 companies see ai as a key revenue driver in 2022 ↗
Modified Source ↗
a bakers dozen of the deals that shaped 2021 page 4 of 5 ↗
Modified Source ↗
a supercomputer more powerful than the human brain may be in reach ↗
Modified Source ↗
above the trend line your industry rumor central for 5 22 2023 ↗
Modified Source ↗
absolutely fabless chip startup funding reaches record 20bn in 2021 ↗
Modified Source ↗
ai business podcast 21 chips should work smarter not harder ↗
Modified Source ↗
ai career notes november 2020 edition ↗
Modified Source ↗
ai departments short staffed ↗
Modified Source ↗
ai equity in business technology an interview with marshall choy of sambanova systems ↗
Modified Source ↗
ai is the new internet but diy ai can leave most enterprises reeling ↗
Modified Source ↗
ai news roundup special edition on generative ai and chatgpt ↗
Modified Source ↗
ai renal care solution identifies high or low risk patients and recommends actions for treatment and care ↗
Modified Source ↗
ai startup sambanova has poached a google cloud vp to run its cloud infrastructure ↗
Modified Source ↗
ai startup sambanova launches new chip designed for higher quality ai ↗
Modified Source ↗
ai supercomputer will run hungarian language models for banking ↗
Modified Source ↗
ai systems startup scales argonnes cosmic cleanup ↗
Modified Source ↗
ai technology is not dark magic its just misunderstood ↗
Modified Source ↗
ai vendor sambanova intros next generation of datascale ↗
Modified Source ↗
amazon launches generative ai play in aws bedrock ↗
Modified Source ↗
announcing the nominees for venturebeats 5th annual women in ai awards ↗
Modified Source ↗
argonne cuts through the noise with sambanova system ↗
Modified Source ↗
aspiration versus action for enterprise ai ↗
Modified Source ↗
big banks will blaze the enterprise gpt 3 ai trail ↗
Modified Source ↗
big data industry predictions for 2023 ↗
Modified Source ↗
bing could finally be better than google but it still wont be more popular experts say ↗
Modified Source ↗
california points to new channel openings ↗
Modified Source ↗
ceo of softbank backed sambanova explains the firms approach to artificial intelligence ↗
Modified Source ↗
changes go far beyond just ai machine learning ↗
Modified Source ↗
chatgpt is just the tip of the iceberg in content creating artificial intelligence get ready for a lot of disruption ↗
Modified Source ↗
cto interview kunle olukotun of sambanova ↗
Modified Source ↗
dialysis lab uses sambanova delorean ai for renal care ↗
Modified Source ↗
eetimes sambanova raises eye popping series d funding ↗
Modified Source ↗
energy digital magazine november drives ai into new computing era for the energy industry pg. 45 53 ↗
Modified Source ↗
enterprises are not making progress on ai risk ceding competitive advantage ↗
Modified Source ↗
ethics of ai benefits and risks of artificial intelligence ↗
Modified Source ↗
eu ai act reaction ais gdpr moment as big tech sounds the alarm ↗
Modified Source ↗
european bank sees path to fastest ai supercomputer ↗
Modified Source ↗
executives weigh risks benefits of emerging technologies ↗
Modified Source ↗
financial services leaders struggle to keep up with ai developments ↗
Modified Source ↗
for users better ai means more personalization ↗
Modified Source ↗
former jaic afrc leader douglas drakeley appointed to sambanova systems advisory board ↗
Modified Source ↗
from rockets to lab grown meat these deals show some of the hottest new startup sectors of 2021 ↗
Modified Source ↗
generative ai solutions for the contact center ↗
Modified Source ↗
getting around the gpt 3 waitlist the hardware way ↗
Modified Source ↗
gitex 2021 sambanova launches first enterprise grade gpt ai powered language model ↗
Modified Source ↗
heard on the street 6 5 2023 ↗
Modified Source ↗
heard on the street 7 19 2023 2 ↗
Modified Source ↗
how ai and ml innovations are driving the need for hardware transformation vb live ↗
Modified Source ↗
how companies are dealing with the talent shortage in data science ↗
Modified Source ↗
how customizing models is bringing generative ai to the enterprise ↗
Modified Source ↗
how enterprise ai use will grow in 2021 predictions from our ai experts ↗
Modified Source ↗
how sambanova systems is navigating shifts in the ai industry ↗
Modified Source ↗
how sambanova systems is tackling dataflow as a service ↗
Modified Source ↗
hr tech predictions 2022 diy ai to accelerate ai deployments across organization ↗
Modified Source ↗
hungarian gov teams up with eastern european bank to develop ai supercomputer ↗
Modified Source ↗
hungarys otp bank invests in ai supercomputer ↗
Modified Source ↗
implementing ai during a worldwide talent shortage ↗
Modified Source ↗
insidebigdata latest news 3 7 2023 ↗
Modified Source ↗
intelligent decision making for capital markets ↗
Modified Source ↗
intelligent decision making for risk managers ↗
Modified Source ↗
investors poured over 13 billion into just 56 ai startups in the first four months of 2021 alone vcs and ceos explain why everyone is trying to cash in ↗
Modified Source ↗
its time for banks to get more intelligent about artificial intelligence ↗
Modified Source ↗
lack of skilled staff limits ai adoption in banking survey finds ↗
Modified Source ↗
london the worlds leader in ai ↗
Modified Source ↗
microsoft unveils chatgpt powered browser and bing search engine ↗
Modified Source ↗
microsoft unveils new bing powered by chatgpt to take on google ↗
Modified Source ↗
new gpt ai powered large language model for banking increases financial services institutions competitiveness and enables accelerated digital transformation 1703560230974 ↗
Modified Source ↗
new sambanova chip designed to handle 5 trillion parameter model ↗
Modified Source ↗
new study reveals more than 78 of companies cite ai as a key revenue driver in 2022 ↗
Modified Source ↗
now a dedicated gpt for the financial industry ↗
Modified Source ↗
nvidia competitor sambanova launches new ai chip ↗
Modified Source ↗
otp bank selects sambanova systems to build europes fastest ai supercomputer ↗
Modified Source ↗
otp group taps sambanova for ai supercomputer ↗
Modified Source ↗
peter buckingham joins sambanova as vp of software engineering ↗
Modified Source ↗
precision accuracy scale and experience all matter with ai ↗
Modified Source ↗
report tech leaders worry the industry may run out of compute power in the next decade ↗
Modified Source ↗
reuters ai chip maker sambanova raises 676 mln valued at over 5 bln ↗
Modified Source ↗
sadiq khan to meet tech giants on trade mission to silicon valley ↗
Modified Source ↗
sambanova adds enterprise grade gpt language modeling to its dataflow as a service platform ↗
Modified Source ↗
sambanova adds gpt banking to its growing dataflow as a service lineup ↗
Modified Source ↗
sambanova adds gpt banking to its growing dataflow as a service lineup 1 ↗
Modified Source ↗
sambanova adds gpt to services expands nlp capabilities ↗
Modified Source ↗
sambanova adds hbm for llm inference chip ↗
Modified Source ↗
sambanova ai launches new chip the sn40l ↗
Modified Source ↗
sambanova aims to meet generative ai challenges ↗
Modified Source ↗
sambanova announces new datascale sn30 hpc system ↗
Modified Source ↗
sambanova announces next gen datascale system ↗
Modified Source ↗
sambanova brings custom silicon to bear on high end ai workloads ↗
Modified Source ↗
sambanova ceo new ai chip brings performance and cost savings ↗
Modified Source ↗
sambanova ceo pre to post ai transition will be bigger than the internet ↗
Modified Source ↗
sambanova doubles up chips to chase ai foundation models ↗
Modified Source ↗
sambanova includes gpt ai powered language in its daas ↗
Modified Source ↗
sambanova injects a little ai mojo into us supercomputer labs nuke sims ↗
Modified Source ↗
sambanova is enabling disruption in the enterprise with ai language models computer vision recommendations and graphs ↗
Modified Source ↗
sambanova launches gpt powered ai purpose built for financial services industry ↗
Modified Source ↗
sambanova launches second gen datascale system ↗
Modified Source ↗
sambanova makes a mark in the ai hardware realm ↗
Modified Source ↗
sambanova opens applications for enterprise ai membership program elevaite ceo rodrigo liang quoted ↗
Modified Source ↗
sambanova research 78 of uk financial services leaders struggle to keep up with ai tech amidst ongoing talent shortage ↗
Modified Source ↗
sambanova ships second generation ai systems ↗
Modified Source ↗
sambanova sn10 rdu at hot chips 33 ↗
Modified Source ↗
sambanova systems announces sambanova gpt banking ↗
Modified Source ↗
sambanova systems gives its integrated ai hardware and software platform a massive performance boost ↗
Modified Source ↗
sambanova systems gpt training program earns high marks ceo rodrigo liang and svp marshall choy quoted ↗
Modified Source ↗
sambanova systems now offers gpt ai powered language model ↗
Modified Source ↗
sambanova systems set to propel otp bank into the age of artificial intelligence ↗
Modified Source ↗
sambanova systems to deliver sambanova datascale to riken ↗
Modified Source ↗
sambanova systems to meet the countrys technology priorities ↗
Modified Source ↗
sambanova systems unveils deep learning platform purpose built for financial services firms ↗
Modified Source ↗
sambanova systems unveils gpt ai powered language model at gitex ↗
Modified Source ↗
sambanova tackles generative ai with new chip and new approach ↗
Modified Source ↗
sambanova unveils gpt banking for financial industry ↗
Modified Source ↗
sambanovas ai paired with fugaku supercomputer to develop digital twins ↗
Modified Source ↗
sambanovas new silicon targets foundation models ↗
Modified Source ↗
silicon valley business journal ai tech startup and nvidia rival sambanova scores 676m at 5b valuation ↗
Modified Source ↗
silicon valley startup sambanova offers new ai system triples previous system speed ↗
Modified Source ↗
siliconangle ai platform startup sambanova systems raises 676m in late stage round ↗
Modified Source ↗
so you think you can design a 20 exaflops computer ↗
Modified Source ↗
softbank leads funding round valuing sambanova at 5 billion ↗
Modified Source ↗
techcrunch sambanova raises 676m at a 5.1b valuation to double down on cloud based ai software for enterprises ↗
Modified Source ↗
technology industry artificial intelligence venture financing deals total 6.1bn globally in april 2021 ↗
Modified Source ↗
techstrong tv ai renaissance marshall choy sambanova ↗
Modified Source ↗
the ai gold rush is alive in silicon valley ↗
Modified Source ↗
weird new things are happening in software says stanford ai professor chris re ↗
Modified Source ↗
ai chip startup sambanova raises 56m from gv and others ↗
Modified Source ↗
ai gets a boost via llnl sambanova collaboration ↗
Modified Source ↗
ai newcomer sambanova gas product lineup and offers new service ↗
Modified Source ↗
ai sambanova breaks cover 450m ai startup with 8 socket ai training solutions and more ↗
Modified Source ↗
ais next act genius chips programmable silicon and the future of computing ↗
Modified Source ↗
googles parent company just made its first ever investment in an a i chip start up 2 ↗
Modified Source ↗
how business leaders should think about ai hardware ↗
Modified Source ↗
its not just ai this is a change in the entire computing industry says sambanova ceo ↗
Modified Source ↗
national lab supercomputing sites pick sambanova for ai system dance ↗
Modified Source ↗
nnsa establishes partnership to accelerate key artificial intelligence computing initiatives ↗
Modified Source ↗
purdue university launches new research center on programming principles and software systems ↗
Modified Source ↗
sambanova delorean ai tech offers kidney treatment guidance to doctors ↗
Modified Source ↗
sambanova emerges from stealth with record breaking ai system ↗
Modified Source ↗
sambanova has been named a 2021 best tech startup by the tech tribune ↗
Modified Source ↗
sambanova unveils purpose built ai machine ↗
Modified Source ↗
software has to lead hardware in the ai dance ↗
Modified Source ↗
startup taps ai to monitor chips ↗
Modified Source ↗
the red hot ai hardware space gets even hotter with 56m for a startup called sambanova systems ↗
Modified Source ↗
top 10 artificial intelligence funding and investments of 2020 ↗
Modified Source ↗
twimlai com twiml talk 211 designing computer systems for software with kunle olukotun ↗
Modified Source ↗