Search result · source text not verified
Full-stack AI platform for inference, fine-tuning, and GPU clusters — powered by cutting-edge research.
Products
Batch InferenceScale to 30 billion tokens per model with any serverless model or private deployment. Start building now Explore the Docs.
Dedicated Model InferenceDeploy any open model in minutes. Roll out safely, scale to meet demand, and keep full control.
Dedicated Container InferenceDeploy video, audio, and avatar generation models on the AI Native Cloud.
GPU ClustersGo from zero to production in minutes. Bare-metal performance, InfiniBand networking, and managed orchestration — with flexible pricing for both on-demand and reserved capacity.
GB200Rent 72 Blackwell GPUs and 36 Grace CPUs in one NVLink domain, built for trillion-parameter training and inference.
The GB200 NVL72 is a liquid-cooled system that connects 72 NVIDIA Blackwell GPUs and 36 Grace CPUs into a single NVLink domain, delivering up to 1.4 exaFLOPS of FP4 compute for trillion-parameter AI. Source ↗
GB300Rent 72 Blackwell Ultra GPUs and 36 Grace CPUs in one NVLink domain, built for AI reasoning and trillion-parameter inference.
The GB300 NVL72 is the Blackwell Ultra system, connecting 72 Blackwell Ultra GPUs and 36 Grace CPUs into one liquid-cooled NVLink domain, with 288GB of HBM3e per GPU and around 1.1 exaFLOPS of FP4 compute, built for AI reasoning and trillion-parameter inference. Source ↗
H100Rent NVIDIA H100 GPUs on demand or reserve a cluster, with 80GB HBM3 and fourth-generation Tensor Cores for large-scale training and inference.
The NVIDIA H100 is a Hopper-architecture data center GPU with 80GB of HBM3 memory, 3.35TB/s of bandwidth, and fourth-generation Tensor Cores with FP8 precision, built for large-scale AI training, LLM inference, and HPC. Source ↗
H2008TB/s for memory-bound LLM inference and training.
The NVIDIA H200 is a Hopper-architecture data center GPU with 141GB of HBM3e memory and 4.8TB/s of bandwidth, the first GPU with HBM3e, built for memory-bound LLM inference and large-scale training. Source ↗
B200Rent NVIDIA Blackwell GPUs on demand or reserve a cluster, with 180GB HBM3e and native FP4 for frontier-scale training and inference.
B300Rent NVIDIA B300 GPUs on demand or reserve a cluster, with 288GB HBM3e and enhanced FP4 for reasoning-scale training and inference.
Serverless InferenceServerless Inference The fastest way to run open-source models on demand. Powered by cutting-edge inference research.
Provisioned ThroughputProvisioned Throughput Committed inference capacity with token-based pricing, reserved throughput, and a 99% uptime SLA.
Managed StorageManaged Storage High-performance managed storage for AI-native workloads. Object storage and parallel filesystems optimized for AI, with zero egress fees.
Fine-TuningFine-Tuning Fine-tune open-source models for production workloads, using the latest research techniques.
No matching products or features.
Customer feedback
Search result · source text not verified
Together AI releases Together Compiler: AI agents continually recompile LLM inference (up to 2.6x TPS over InferenceX best)
Search result · source text not verified
Anyone moved away from Together.ai? Looking for alternatives
Search result · source text not verified
Case Study: Together AI's entire GTM is basically "give stuff away until you become unavoidable"
Search result · source text not verified
Interviewed with Together AI recently? (New grad) looking for insights & tips
Search result · source text not verified
Case Study: Together AI's entire GTM is basically "give stuff ...
Been studying Together AI's growth lately and honestly their strategy is kind of underrated in how simple it is.
Search result · source text not verified
[D] Together AI hits $100M in ARR but it just resales compute
[D] Together AI hits $100M in ARR but it just resales compute - hype? ... I recently learned that this startup is seen as the fastest revenue ramp ...
Search result · source text not verified
OpenRouter vs Together AI : r/AI_Agents
together.ai is very fast but just one provider and not necessarily inexpensive. OpenRouter will rotate through multiple providers to find ...
Search result · source text not verified
Best Generative AI Infrastructure Software
Read Together.ai Reviews. What do users say? ... Per-token billing with committed capacity as an alternative: AWS Bedrock prices on-demand usage per model, offers ...
Search result · source text not verified
Read Customer Service Reviews of together.ai
Contact info. Anguilla. together.ai. 2.5. Poor. TrustScore 2.5 out of 5. 9 reviews ... See how their reviews and ratings are sourced, scored, and moderated.
Search result · source text not verified
Together.ai Software Reviews, Demo & Pricing - 2026
Review of Together.ai Software: system overview, features, price and cost information. Get free demos and compare to similar programs.
Search result · source text not verified
The Data Platform Behind Together AI's $3.3B Scale
The Data Platform Behind Together AI's $3.3B Scale · #1 fastest on 100GB benchmarks vs. Redshift, Athena, and ClickHouse · 128 self-service users- product teams, ...
Search result · source text not verified
Together AI Review 2026 — The AI-Native Cloud Expert Guide
Expert 2026 review of Together AI. Analyze serverless inference costs, $5 free credits, and dedicated GPU endpoints for Llama 4 and DeepSeek.
Search result · source text not verified
Together AI's Post
Serving MiniMax-M3 on Together AI: sparse attention, paged decode, and multimodal preprocessing at production scale ... Customer Experience ...
Search result · source text not verified
Qwen3.6-35B-A3B: Agentic coding power, now open to all
... batch inference. But you're right that it's quite related. The llama.cpp ... I think I saw Together.ai with that offering, but for some reason just ...
No feedback found.
Marketing & Ads
MetaTogether AIActive
Original ad ↗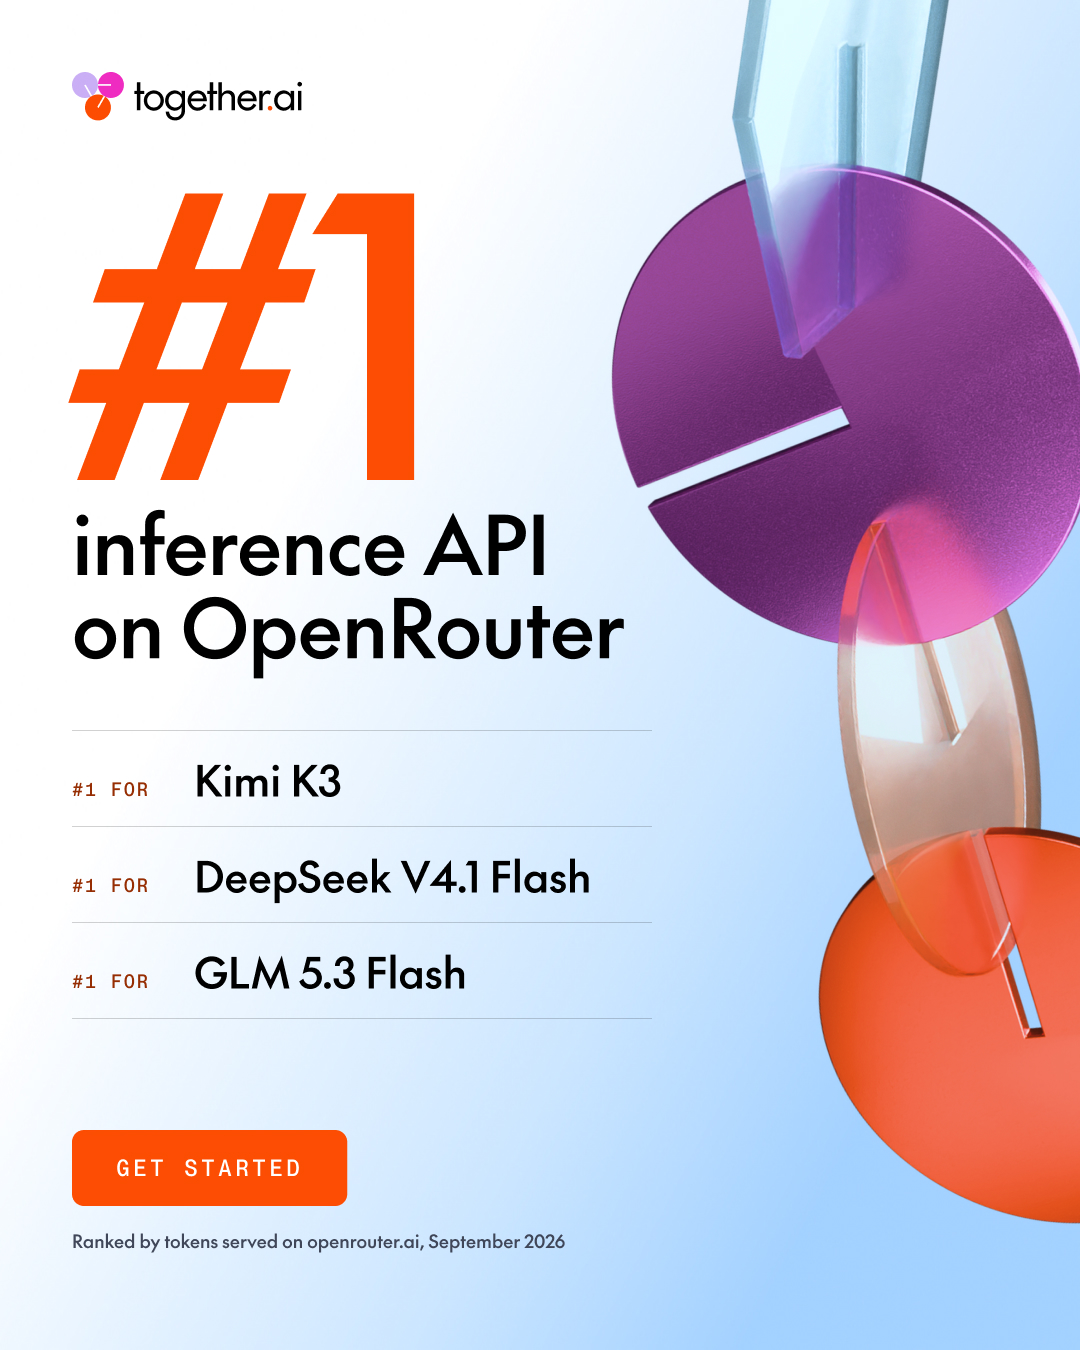
Put open models into production
Evaluating GLM-5.3, DeepSeek V4.1 Flash, or Kimi K3? Run them through Together AI Serverless Inference, a fully managed API built for production workloads. Talk with our team about model fit, performance, and the path from evaluation to production.
See details
First shown Nov 9, 2026 · Last shown Nov 10, 2026Landing page
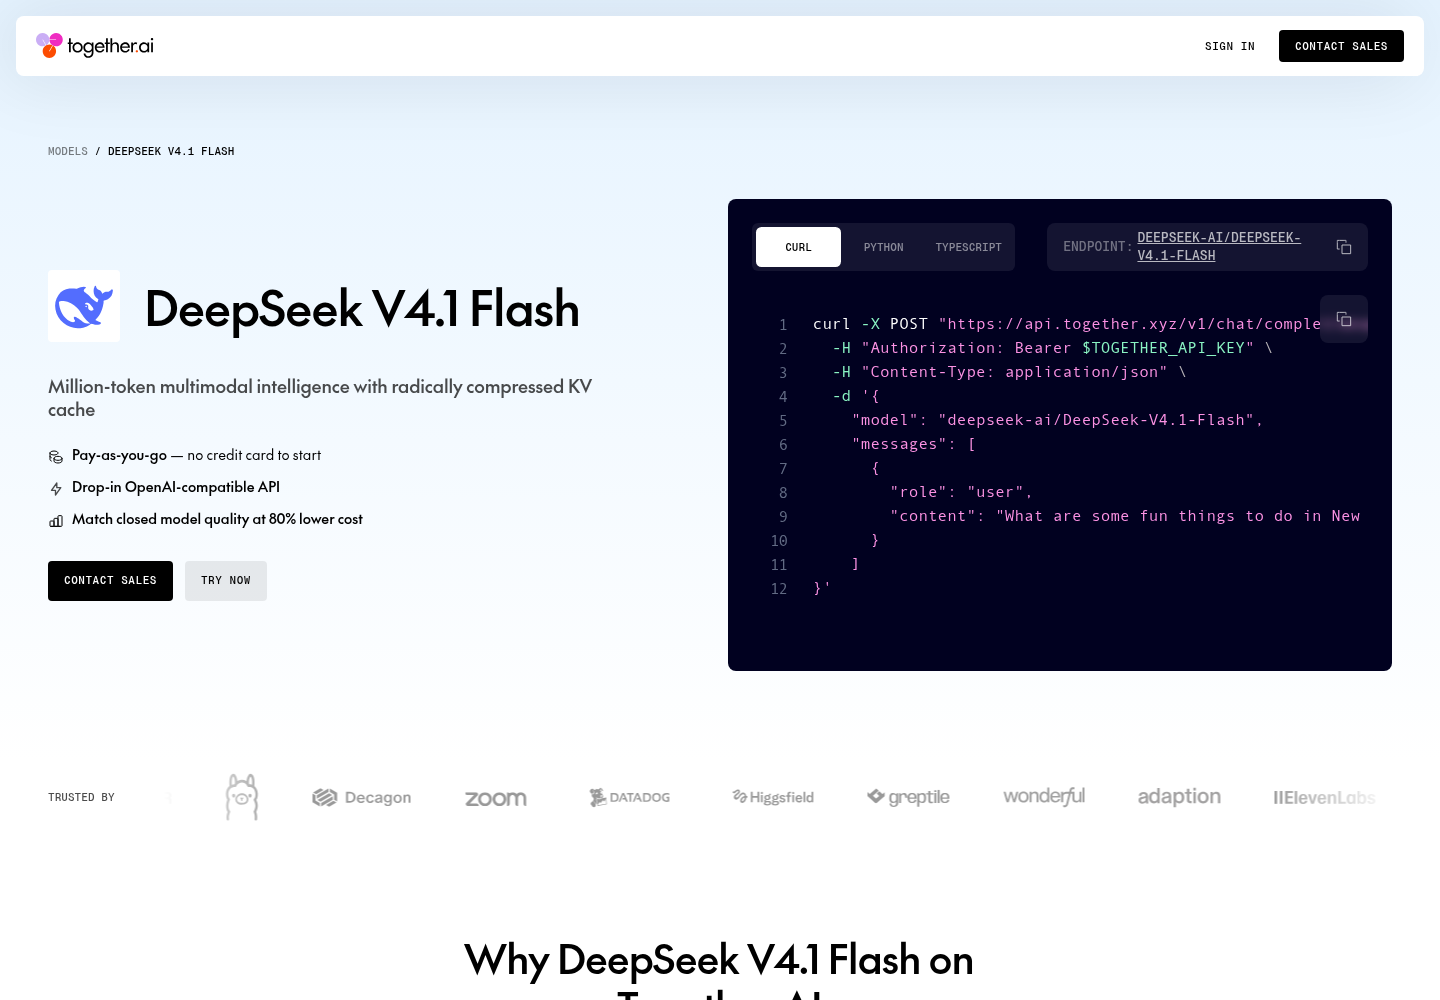 Captured Nov 11, 2026DeepSeek V4.1 Flash API: Pricing, Benchmarks & Docs | Together AI ↗
MetaTogether AIActive
Original ad ↗Put open models into production
Evaluating GLM-5.3, DeepSeek V4.1 Flash, or Kimi K3? Run them through Together AI Serverless Inference, a fully managed API built for production workloads. Talk with our team about model fit, performance, and the path from evaluation to production.
See details
First shown Nov 9, 2026 · Last shown Nov 9, 2026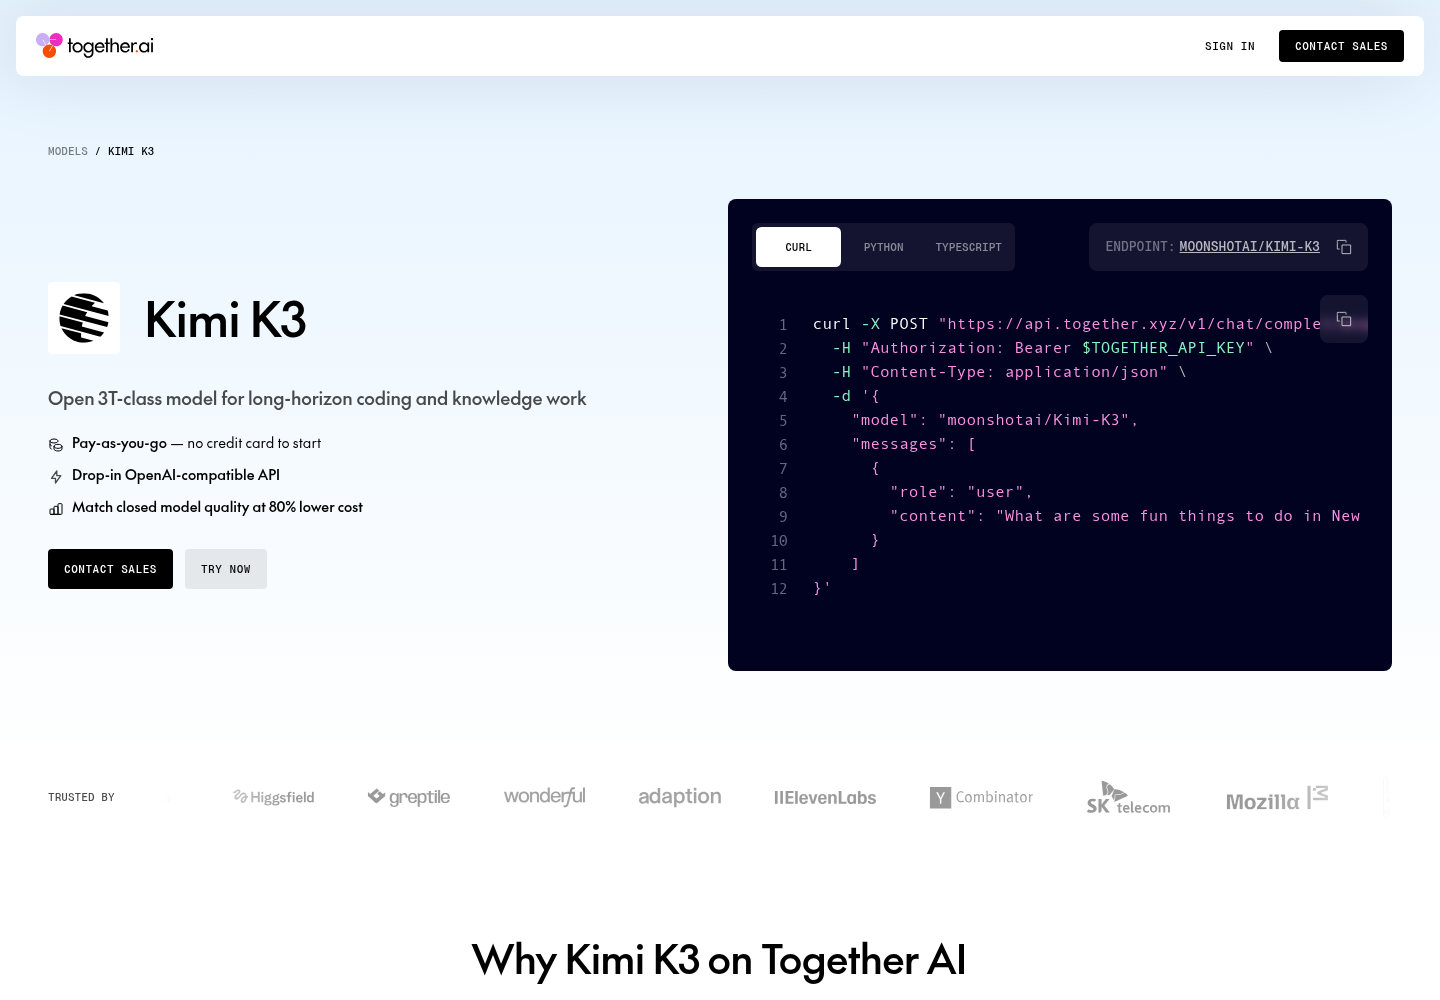
MetaTogether AIActive
Original ad ↗Put open models into production
Evaluating GLM-5.3, DeepSeek V4.1 Flash, or Kimi K3? Run them through Together AI Serverless Inference, a fully managed API built for production workloads. Talk with our team about model fit, performance, and the path from evaluation to production.
See details
First shown Nov 9, 2026 · Last shown Nov 10, 2026Landing page
Captured Nov 11, 2026DeepSeek V4.1 Flash API: Pricing, Benchmarks & Docs | Together AI ↗MetaTogether AIActive
Original ad ↗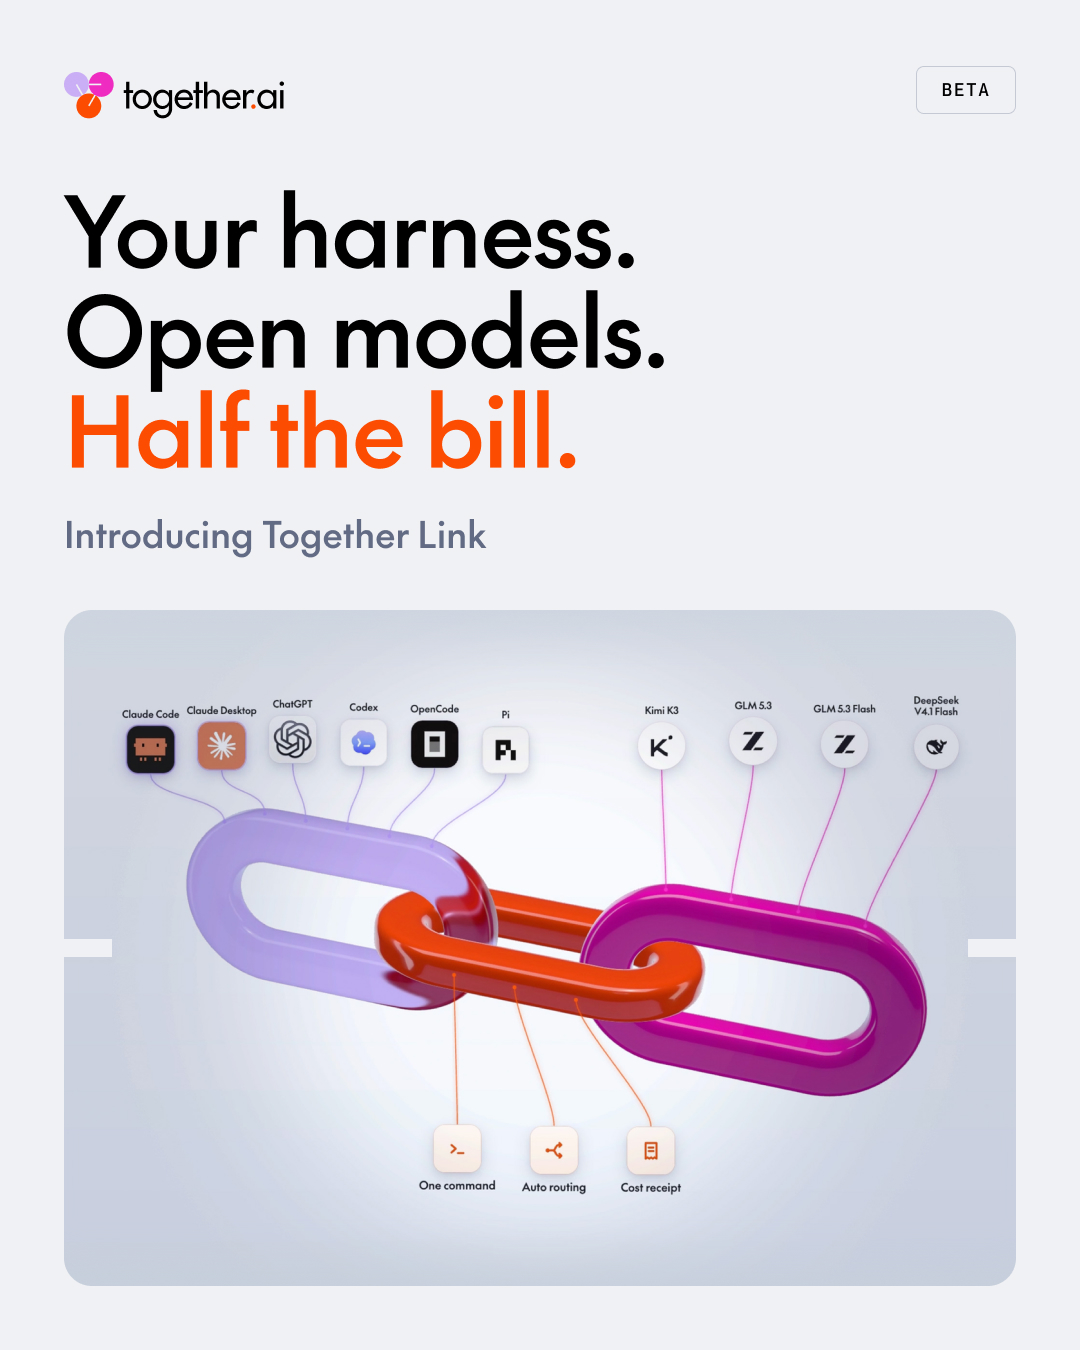
Introducing Together Link: same agent, a fraction of the bill
Your coding agent doesn't need an expensive closed model for every task. Together Link runs frontier open models like Kimi K3 and GLM 5.3 inside the harness your team already uses, including Claude Code, Codex, OpenCode and Pi. Same workflow, over 50% less spend.
See details
First shown Oct 26, 2026 · Last shown Nov 10, 2026Landing page
 Captured Nov 11, 2026Together Link: open models in the harness you already use. Start with one command today. ↗
MetaTogether AIActive
Original ad ↗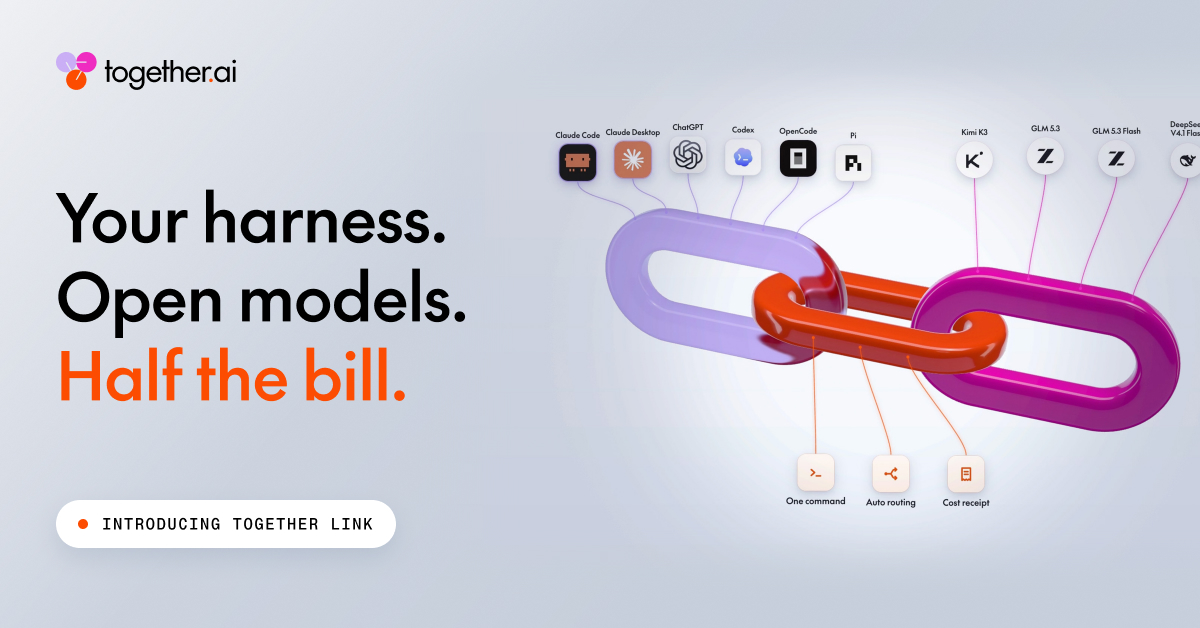
Introducing Together Link: same agent, a fraction of the bill
Your coding agent doesn't need an expensive closed model for every task. Together Link runs frontier open models like Kimi K3 and GLM 5.3 inside the harness your team already uses, including Claude Code, Codex, OpenCode and Pi. Same workflow, over 50% less spend.
See details
First shown Oct 26, 2026 · Last shown Nov 10, 2026Landing page
Captured Nov 11, 2026Together Link: open models in the harness you already use. Start with one command today. ↗MetaTogether AIActive
Original ad ↗
For training and inference
No H100s? No H200s? No B200s? Together AI has all three available on demand, right now.
See details
First shown Oct 16, 2026 · Last shown Nov 10, 2026
MetaTogether AIActive
Original ad ↗
For training and inference
No H100s? No H200s? No B200s? Together AI has all three available on demand, right now.
See details
First shown Oct 16, 2026 · Last shown Nov 10, 2026GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Oct 16, 2026 · Last shown Nov 11, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInTogether AI
Original ad ↗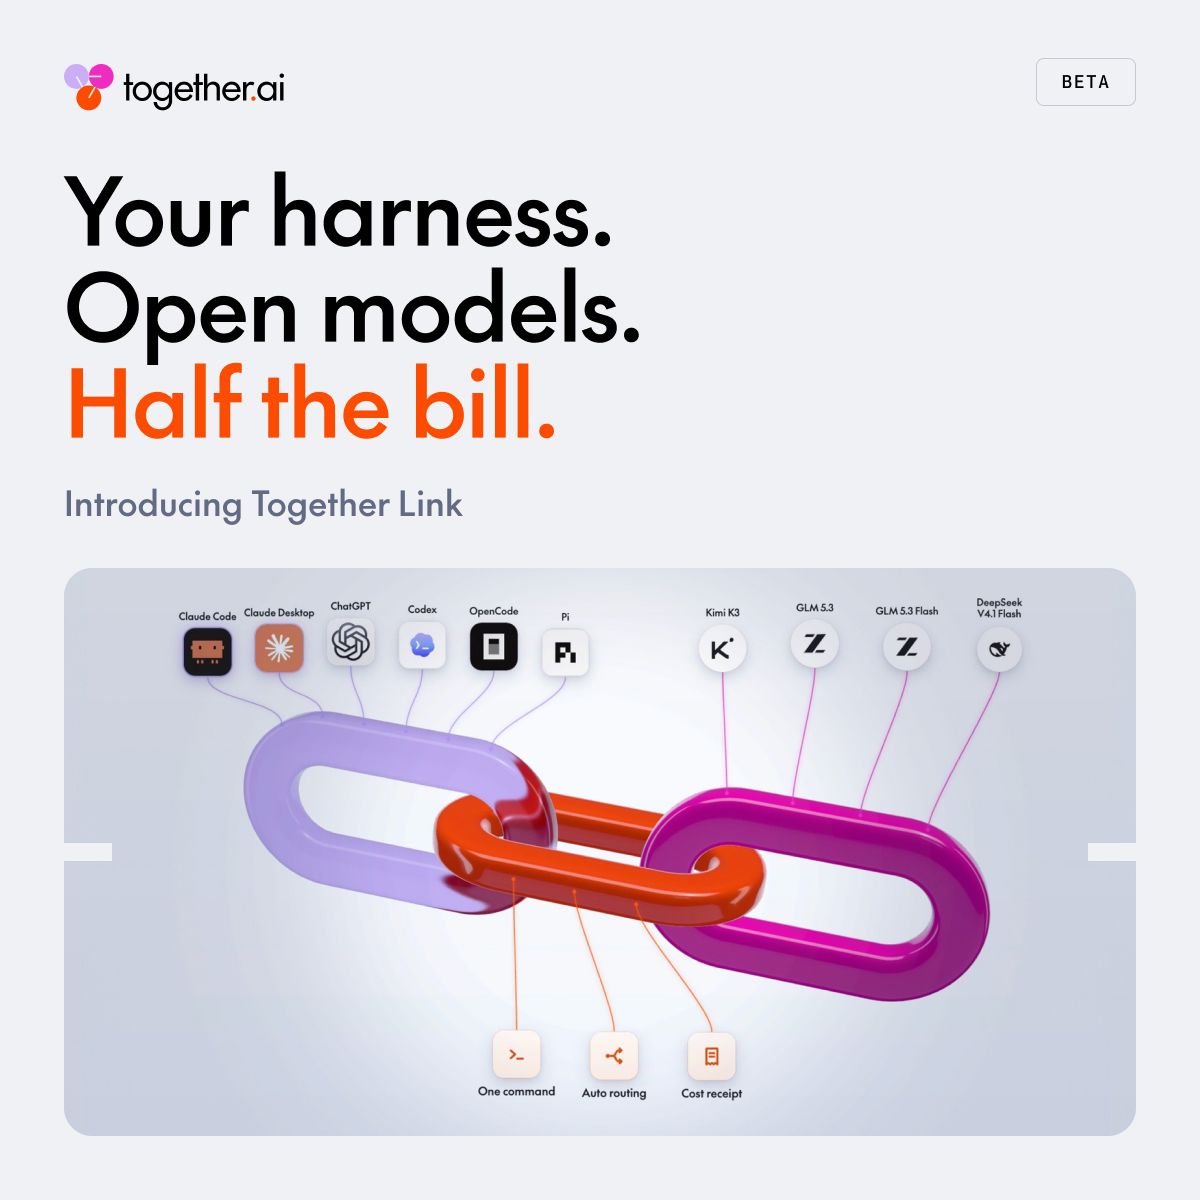
Introducing Together Link: same agent, a fraction of the bill
Your coding agent doesn't need an expensive closed model for every task. Together Link runs frontier open models like Kimi K3 and GLM 5.3 inside the harness your team already uses, including Claude Code, Codex, OpenCode and Pi. Same workflow, over 50% less spend.
Learn more
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInTogether AI
Original ad ↗Frontier open models in the harness you already use
Keep your coding agent. Change the bill. Together Link connects Claude Code, Codex and more to top open models on Together AI with one install command. Your settings and logins stay put, and switching back takes one command.
Learn more
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInTogether AI
Original ad ↗
The fastest output. The best token economics at scale.
Hedra cut cloud costs 60%. Decagon achieved 6× cost reduction per turn. Together Inference, built for unit economics that hold at scale.
Learn more
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInTogether AI
Original ad ↗
A capacity agreement built for production.
A token-based capacity agreement for frontier open models. Together Provisioned Throughput: built for teams migrating off closed APIs.
Learn more
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗Inference built for production
Fine-tune and deploy open models on infrastructure built for the full workflow.
First shown Nov 9, 2026 · Last shown Nov 11, 2026
GoogleTOGETHER COMPUTER, INC.
Original ad ↗Inference built to scale
Fine-tune and deploy open models on infrastructure built for the full workflow.
First shown Nov 9, 2026 · Last shown Nov 11, 2026GoogleTOGETHER COMPUTER, INC.
Original ad ↗
Inference built to scale
Fine-tune and deploy open models on infrastructure built for the full workflow.
First shown Nov 9, 2026 · Last shown Nov 11, 2026LinkedInTogether AI
Original ad ↗
Run open models in your coding agent in minutes
One command. Your coding agent, now running on open models. Watch Together Link connect Claude Code, Claude Desktop and Codex to Kimi K3, GLM 5.3, MiniMax M3, and DeepSeek V4.1 Flash. Every session ends with a receipt showing exactly what it cost.
Learn more
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Apr 10, 2026 · Last shown Nov 11, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInTogether AI
Original ad ↗The fastest output. The best token economics at scale.
Hedra cut cloud costs 60%. Decagon achieved 6× cost reduction per turn. Together Inference, built for unit economics that hold at scale.
Learn more
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Sep 24, 2026 · Last shown Nov 11, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Apr 10, 2026 · Last shown Nov 11, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Apr 10, 2026 · Last shown Nov 11, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInTogether AI
Original ad ↗Frontier models. Token-based pricing. Economics that scale.
Up to 90% lower cost than closed frontier APIs. Together Provisioned Throughput: reserved capacity, predictable pricing, and an SLA built for production.
Learn more
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Sep 24, 2026 · Last shown Nov 11, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Sep 24, 2026 · Last shown Nov 11, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Sep 24, 2026 · Last shown Nov 11, 2026
Landing page unavailable: the ad source did not supply a destination URL.
LinkedInTogether AI
Original ad ↗The fastest output. The best token economics at scale.
Hedra cut cloud costs 60%. Decagon achieved 6× cost reduction per turn. Together Inference, built for unit economics that hold at scale.
Learn more
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Sep 22, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Sep 22, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Sep 22, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
GoogleTOGETHER COMPUTER, INC.
Original ad ↗ First shown Sep 24, 2026 · Last shown Nov 10, 2026
Landing page unavailable: the ad source did not supply a destination URL.
New pages
Polymorphic Inference: self-tuning inference for open models ↗
Together Compiler: Continual Compilation for AI inference ↗
Auto repair for Together GPU Clusters: from GPU fault to healthy node ↗
Together Post-Training: frontier-grade model shaping, the way that fits you ↗
Meta Muse Spark Open is live on Together AI ↗
Expanding our enterprise inference capacity with IBM Cloud and NVIDIA ↗
Together Link: open models in the harness you already use. Start with one command today. ↗
How to train your own Jev for $17 ↗
Canary rollouts: upgrade models in production without downtime ↗
How a global fintech scaled coding agent traffic with Dedicated Model Inference ↗
Migrating from closed to open source models, Together ↗
Together AI expands fine-tuning service with more models, live metrics, and finer controls ↗
Introducing preemptible compute: the same compute, half the price ↗
To Infinity and Beyond: ThunderKittens Now on NVIDIA Vera Rubin NVL72! ↗
The Open Source AI Stack ↗
glm 5 3 vs glm 5 3 flash on deepswe cost coding and routing ↗
GLM-5.3 vs. Claude Fable 5 on DeepSWE: Cost, Coding, and Routing ↗
GLM-5.3 vs. GPT-5.6 Sol on DeepSWE: Cost, Coding, and Routing ↗
deepseek v4 pro 0813 vs gpt 5 6 sol on deepswe cost coding and routing ↗
A/B test models in production ↗
DeepSeek V4 Pro 0813 vs Claude Fable 5 on DeepSWE: Cost, Coding, and Routing ↗
DeepSeek-V4 Flash 0731 vs GPT-5.6 Luna on DeepSWE: Cost and Coding ↗
Kimi K3: the complete developer guide ↗
Autoscaling endpoints for LLM inference ↗
Configuring Dedicated Model Inference ↗
ThunderAgent: 2x Faster Agentic Inference for Synthetic Data Generation at Scale ↗
Together AI announces strategic partnership with Moonshot AI to natively serve Kimi models ↗
kimi k3 vs gpt 5 6 sol on deepswe cost coding and routing ↗
kimi k3 vs claude fable 5 on deepswe cost and coding ↗
The production platform for open-weight AI inference ↗
Together AI and Y Combinator partner to launch the first dedicated GPU cluster for the YC community ↗
What does 99.9% uptime mean for inference? ↗
New in Together GPU Clusters: Reliability and control for production GPU clusters ↗
Together AI brings Thinking Machines Lab’s new model Inkling on day 0 ↗
provisioned throughput ↗
Announcing our $800M Series C to accelerate the shift to open-source AI ↗
Together AI at ICML 2026: frontier research across the full stack ↗
ParallelKernelBench: Frontier LLMs can't write fast multi-GPU kernels (yet) ↗
Kimi K2.7 Code vs Claude Fable 5: Landing pages that cost 94% less ↗
Building trust in enterprise AI: Together AI earns ISO 27001:2022 certification ↗
Serving MiniMax-M3 for efficient inference: Unlocking 1M-Token Context and Multimodality Without Regrets ↗
How Together AI built the world’s fastest speech-to-text stack ↗
Benchmarking inference at scale: coding agents ↗
Together AI and Pearl Research Labs Team Up to Reduce the Cost of AI Inference ↗
Violin: An open-source video translation skill that breaks language barriers ↗
introducing voice finder a new tool to quickly find the right voice for your app from over 600 voices ↗
Serving DeepSeek-V4: why million-token context is an inference systems problem ↗
Deploy and inference any model from HuggingFace ↗
Foundational research powering efficient inference at scale ↗
Announcing Together AI and Adaption Partnership ↗
From 732 bytes to nowhere: shutting down Copy Fail in production ↗
DeepSeek-V4 Pro now available on Together AI ↗
Together AI Brings NVIDIA Nemotron 3 Nano Omni to Developers on Day 0 ↗
Accelerate RL rollouts by up to 50% with distribution-aware speculative decoding ↗
Capacity without conflict: A guide to multi-tenant GPU cluster design for AI-native teams ↗
Parcae: Doing more with fewer parameters using stable looped models ↗
EinsteinArena: Harnessing the collective intelligence of agents in the wild to advance science ↗
What is an AI Native Cloud? ↗
AI for Systems: Using LLMs to Optimize Database Query Execution ↗
wan 2 7 now available on together ai ↗
deepgram speech to text and voice models now available natively on together ai ↗
Inside the Together AI kernels team ↗
Aurora ↗
Plan, divide, and conquer: How weak models excel at long context tasks ↗
Together AI expands fine-tuning service with tool calling, reasoning, and vision support ↗
Mamba-3 ↗
Together AI at NVIDIA GTC 2026: Explore our latest innovations across research and products ↗
Deploy real-time voice agents for every use case ↗
Build real-time voice agents on Together AI ↗
Together AI Brings NVIDIA Nemotron 3 to Developers on Day 0 ↗
New in Together GPU Clusters: Autoscaling, observability, and self-healing ↗
Key research and product announcements at the AI Native Conf ↗
FlashAttention-4: Algorithm and Kernel Pipelining Co-Design for Asymmetric Hardware Scaling ↗
Cache-aware prefill–decode disaggregation (CPD) for up to 40% faster long-context LLM serving ↗
Introducing Together AI’s new look ↗
coderforge preview ↗
How speech models fail where it matters the most and what to do about it ↗
Consistency diffusion language models: Up to 14x faster inference without sacrificing quality ↗
Introducing Dedicated Container Inference: Delivering 2.6x faster inference for custom AI models ↗
What do LLMs think when you don't tell them what to think about? ↗
rime arcana v3 turbo and rime arcana v3 now available on together ai ↗
Together AI welcomes Alon Gavrielov as VP of Infrastructure Strategy ↗
Fine-tuning open LLM judges to outperform GPT-5.2 ↗
Together Evaluations now supports comparing top commercial APIs vs. open source models ↗
DSGym: A holistic framework for evaluating and training data science agents ↗
Optimizing inference speed and costs: Lessons learned from large-scale deployments ↗
Learn how Cursor partnered with Together AI to deliver real-time, low-latency inference at scale ↗
Inside multi-node training: How to scale model training across GPU clusters ↗
How to choose the right open model for production ↗
MiniMax Speech 2.6 Turbo now available natively on Together AI ↗
Rime voice models now available on Together AI ↗
Research POV: Yes, AGI Can Happen – A Computational Perspective ↗
Announcing native availability of NVIDIA Nemotron 3 Nano, NVIDIA’s latest reasoning model ↗
Announcing Together Python SDK v2.0 ↗
Introducing AutoJudge: Streamlined inference acceleration via automated dataset curation ↗
Together AI and Meta partner to bring PyTorch Reinforcement Learning to the AI Native Cloud ↗
How to run TorchForge reinforcement learning pipelines in the Together AI Native Cloud ↗
Together AI delivers fastest inference for the top open-source models ↗
FLUX.2: Multi-reference image generation now available on Together AI ↗
Modified Source ↗
Arcana v2 ↗
Modified Source ↗
Deepgram Aura-2 ↗
Modified Source ↗
Boreal-H3 ↗
Modified Source ↗
ByteDance Seedance 1.0 Lite ↗
Modified Source ↗
bytedance seedream 3 0 ↗
Modified Source ↗
bytedance seedream 4 0 ↗
Modified Source ↗
cartesia sonic 3 ↗
Modified Source ↗
cartesia sonic 35 ↗
Modified Source ↗
cartesia sonic v1 ↗
Modified Source ↗
cogito v1 preview llama 70b ↗
Modified Source ↗
cogito v1 preview qwen 14b ↗
Modified Source ↗
cogito v1 preview qwen 32b ↗
Modified Source ↗
cogito v2 1 671b ↗
Modified Source ↗
deepseek r1 distilled llama 70 ↗
Modified Source ↗
deepseek r1 distilled qwen 14 ↗
Modified Source ↗
deepseek v3 ↗
Modified Source ↗
deepseek v4 1 flash ↗
Modified Source ↗
deepseek v4 1 flash 1017 ↗
Modified Source ↗
deepseek v4 flash 0731 ↗
Modified Source ↗
deepseek v4 pro 0813 ↗
Modified Source ↗
devstral small 2505 ↗
Modified Source ↗
elorian glimpse ↗
Modified Source ↗
flux ↗
Modified Source ↗
flux 1 kontext max ↗
Modified Source ↗
flux 1 kontext pro ↗
Modified Source ↗
flux 2 flex ↗
Modified Source ↗
flux 2 pro ↗
Modified Source ↗
gemini 31 flash image ↗
Modified Source ↗
gemini 31 flash lite image ↗
Modified Source ↗
gemma 3 12b ↗
Modified Source ↗
gemma 3 1b ↗
Modified Source ↗
gemma 3 27b ↗
Modified Source ↗
gemma 3 4b ↗
Modified Source ↗
gemma 3n e4b it ↗
Modified Source ↗
gemma 4 31b ↗
Modified Source ↗
gemma 4 31b it pearl ↗
Modified Source ↗
gemma instruct 2b ↗
Modified Source ↗
glm 4 5 air ↗
Modified Source ↗
glm 4 7 ↗
Modified Source ↗
glm 5 ↗
Modified Source ↗
glm 5 3 ↗
Modified Source ↗
glm 5 3 flash ↗
Modified Source ↗
glm 51 ↗
Modified Source ↗
glm 52 ↗
Modified Source ↗
google veo 3 0 ↗
Modified Source ↗
google veo 3 1 ↗
Modified Source ↗
google veo 3 1 lite ↗
Modified Source ↗
gpt oss 120b ↗
Modified Source ↗
ideogram 3 0 ↗
Modified Source ↗
inkling ↗
Modified Source ↗
inkling small ↗
Modified Source ↗
juggernaut lightning flux ↗
Modified Source ↗
juggernaut pro flux ↗
Modified Source ↗
kimi k27 code ↗
Modified Source ↗
kimi k3 ↗
Modified Source ↗
kimi k3 1 pro ↗
Modified Source ↗
kokoro 82m ↗
Modified Source ↗
liquid lfm2 5 8b a1b ↗
Modified Source ↗
llama 3 1 70b ↗
Modified Source ↗
llama 3 3 70b ↗
Modified Source ↗
llama 3 8b instruct lite ↗
Modified Source ↗
llama guard 4 12b ↗
Modified Source ↗
magistral small 2506 ↗
Modified Source ↗
minimax h3 ↗
Modified Source ↗
minimax m1 40k ↗
Modified Source ↗
minimax m1 80k ↗
Modified Source ↗
minimax m2 5 ↗
Modified Source ↗
minimax m2 7 ↗
Modified Source ↗
minimax m3 ↗
Modified Source ↗
minimax m3 1 flash ↗
Modified Source ↗
minimax speech 2 6 turbo ↗
Modified Source ↗
ministral 3 14b instruct 2512 ↗
Modified Source ↗
mist v2 ↗
Modified Source ↗
mistral instruct ↗
Modified Source ↗
mistral small 3 ↗
Modified Source ↗
muse glimmer ↗
Modified Source ↗
muse spark open ↗
Modified Source ↗
nemotron 3 5 super vl ↗
Modified Source ↗
nemotron 3 asr streaming 0 6b ↗
Modified Source ↗
nim llama 3 1 70b instruct ↗
Modified Source ↗
nim llama 3 1 8b instruct ↗
Modified Source ↗
nim llama 3 1 nemotron 70b instruct ↗
Modified Source ↗
nim llama 3 2 11b vision instruct ↗
Modified Source ↗
nim llama 3 2 90b vision instruct ↗
Modified Source ↗
nim llama 3 3 70b instruct ↗
Modified Source ↗
nim llama 3 3 nemotron super 49b v1 ↗
Modified Source ↗
nim mistral nemo 12b instruct ↗
Modified Source ↗
nim mixtral 8x22b instruct v0 1 ↗
Modified Source ↗
nim mixtral 8x7b instruct v0 1 ↗
Modified Source ↗
nova 3 ↗
Modified Source ↗
nova 3 multilingual ↗
Modified Source ↗
nvidia nemotron 3 nano ↗
Modified Source ↗
nvidia nemotron 3 nano omni ↗
Modified Source ↗
nvidia nemotron 3 super ↗
Modified Source ↗
nvidia nemotron 35 asr ↗
Modified Source ↗
nvidia nemotron nano 9b v2 ↗
Modified Source ↗
orpheus tts ↗
Modified Source ↗
p image ideogram ↗
Modified Source ↗
parakeet tdt 0 6b v3 ↗
Modified Source ↗
parakeet tdt 0 6b v3 realtime ↗
Modified Source ↗
pixverse v5 6 ↗
Modified Source ↗
pixverse v6 ↗
Modified Source ↗
prism ml ternary bonsai 27b ↗
Modified Source ↗
qwen 2 5 ↗
Modified Source ↗
qwen 2 5 coder 32b instruct ↗
Modified Source ↗
qwen image ↗
Modified Source ↗
qwen image 20 ↗
Modified Source ↗
qwen image 20 pro ↗
Modified Source ↗
qwen qwq 32b ↗
Modified Source ↗
qwen2 5 vl 72b instruct ↗
Modified Source ↗
qwen3 0 6b ↗
Modified Source ↗
qwen3 0 6b base ↗
Modified Source ↗
qwen3 1 7b ↗
Modified Source ↗
qwen3 1 7b base ↗
Modified Source ↗
qwen3 14b base ↗
Modified Source ↗
qwen3 235b a22b instruct 2507 fp8 ↗
Modified Source ↗
qwen3 30b a3b ↗
Modified Source ↗
qwen3 30b a3b base ↗
Modified Source ↗
qwen3 32b ↗
Modified Source ↗
qwen3 4b ↗
Modified Source ↗
qwen3 4b base ↗
Modified Source ↗
qwen3 5 397b a17b ↗
Modified Source ↗
qwen3 5 9b ↗
Modified Source ↗
qwen3 6 35b a3b fp8 ↗
Modified Source ↗
qwen3 8 max ↗
Modified Source ↗
qwen3 8b ↗
Modified Source ↗
qwen3 next 80b a3b thinking ↗
Modified Source ↗
qwen3 vl 32b instruct ↗
Modified Source ↗
qwen36 plus ↗
Modified Source ↗
qwen37 max ↗
Modified Source ↗
qwen37 plus ↗
Modified Source ↗
reflection beam ↗
Modified Source ↗
ripple 65b preview ↗
Modified Source ↗
salesforce llamarank ↗
Modified Source ↗
sd xl ↗
Modified Source ↗
seedream 50 lite ↗
Modified Source ↗
step 5 preview ↗
Modified Source ↗
ternary bonsai 2 27b ↗
Modified Source ↗
tev1 4b experimental ↗
Modified Source ↗
trinity mini ↗
Modified Source ↗
vidu 2 0 ↗
Modified Source ↗
vidu q1 ↗
Modified Source ↗
vidu q3 ↗
Modified Source ↗
vidu q3 turbo ↗
Modified Source ↗
wan 2 2 i2v ↗
Modified Source ↗
wan 2 2 t2v ↗
Modified Source ↗
wan 27 ↗
Modified Source ↗
wan 27 edit ↗
Modified Source ↗
wan 27 i2v ↗
Modified Source ↗
wan 27 r2v ↗
Modified Source ↗
fine tuning ↗
Modified Source ↗
pricing ↗
Modified Source ↗
pricing capacity ↗
Modified Source ↗
careers ↗
Modified Source ↗
GPU infrastructure purpose-built for generative media workloads ↗
Modified Source ↗
provisioned throughput ↗
Modified Source ↗
post training ↗
Modified Source ↗
Blog ↗
Modified Source ↗
evaluations ↗
Modified Source ↗
Manufacture intelligence at industrial scale ↗
Modified Source ↗
managed storage ↗
Modified Source ↗
Reliable self-serve, AI-ready GPU clusters at scale ↗
Modified Source ↗
sandbox ↗
Modified Source ↗
Process massive workloads asynchronously ↗
Modified Source ↗
switch to open models ↗
Modified Source ↗
The AI Native Cloud making headlines ↗
Modified Source ↗
serverless inference ↗
Modified Source ↗
support ↗
Modified Source ↗
Contact sales ↗
Modified Source ↗
accelerated compute ↗
Modified Source ↗
breakthrough island neurips 2026 ↗
Modified Source ↗
together table neurips edition ↗
Modified Source ↗
events ↗
Modified Source ↗
brand ↗
Modified Source ↗
a deep dive into nvidia blackwell ↗
Modified Source ↗
build code agent from scratch ↗
Modified Source ↗
codesandbox sdk webinar ↗
Modified Source ↗
deepseek r1 how it works simplified together ai webinar ↗
Modified Source ↗
everything you need to know about kimi k3 a conversation with moonshot ai and together ai ↗
Modified Source ↗
how advanced tool calling transforms agentic use cases ↗
Modified Source ↗
openais gpt oss deep dive into how it works ↗
Modified Source ↗
cookbooks ↗
Modified Source ↗
demos ↗
Modified Source ↗
Leading open models, ready for production ↗
Modified Source ↗
research ↗
Modified Source ↗
research blog ↗
Modified Source ↗
customers ↗
Modified Source ↗
Request project plan ↗
Modified Source ↗
Model Shaping ↗
Modified Source ↗
startup accelerator ↗
Modified Source ↗
Model Shaping ↗
Modified Source ↗
research credits program request ↗
Modified Source ↗
ai native conf terms and conditions ↗
Modified Source ↗
ainativeconf ↗
Modified Source ↗
cookie policy ↗
Modified Source ↗
cursor and decagon gtc ↗
Modified Source ↗
terms of service ↗
Modified Source ↗
about us ↗
Together Products ↗
Modified Source ↗
Dedicated inference, tuned for production ↗
Modified Source ↗
open model roi calculator ↗
Modified Source ↗
Model Shaping ↗
Modified Source ↗
nvidia ↗
Modified Source ↗
request access custom training ↗
Modified Source ↗
polymorphic inference ↗
Modified Source ↗
link ↗
Modified Source ↗
neurips 2026 ↗
Modified Source ↗
deepseek v3 1 hybrid thinking model now available on together ai ↗
Announcing the fastest inference for realtime voice AI agents ↗
Modified Source ↗
mixtral ↗
Modified Source ↗
mistral small 3 api now available on together ai a new category leader in small models ↗
Modified Source ↗
decagon ↗
Modified Source ↗
deep cogito ↗
Modified Source ↗
greptile ↗
Modified Source ↗
build ultra low latency voice ai applications with together ai and cartesia sonic ↗
Modified Source ↗
deepswe ↗
How to evaluate and benchmark Large Language Models (LLMs) ↗
Modified Source ↗
flux 1 kontext ↗
Modified Source ↗
flux api is now available on together ai new pro free access to flux schnell ↗
Modified Source ↗
flux tools models together apis canny depth image generation ↗
Modified Source ↗
futurebench ↗
Modified Source ↗
generate images with specific styles using flux loras on together ai ↗
Modified Source ↗
how to build a real time image generator with together ai ↗
Modified Source ↗
introducing together evaluations ↗
Modified Source ↗
llama 3 2 vision stack ↗
Modified Source ↗
llama 3 3 ↗
Modified Source ↗
llama 31 quality ↗
Modified Source ↗
llama 4 ↗
Modified Source ↗
nvidia ai foundry partnership ↗
Modified Source ↗
nvidia blackwell test drive ↗
Modified Source ↗
redpajama ↗
Modified Source ↗
safety models ↗
Modified Source ↗
speech to text whisper apis ↗
Modified Source ↗
the mamba in the llama distilling and accelerating hybrid models ↗
Modified Source ↗
together rerank api and salesforce llamarank ↗
Modified Source ↗
yutori ↗
Modified Source ↗
llama 4 maverick ↗
Modified Source ↗
llama 4 scout ↗
Modified Source ↗
nano banana pro ↗
Modified Source ↗
cogito v1 preview llama 3b ↗
Modified Source ↗
google imagen 4 0 fast ↗
Modified Source ↗
google imagen 4 0 preview ↗
Modified Source ↗
google imagen 4 0 ultra ↗
Modified Source ↗
google veo 2 0 ↗
Modified Source ↗
kling 1 6 standard ↗
Modified Source ↗
kling 2 1 master ↗
Modified Source ↗
kling 2 1 pro ↗
Modified Source ↗
kling 2 1 standard ↗
Modified Source ↗
nemotron 3 5 lightning ↗
Modified Source ↗
sora 2 ↗
Modified Source ↗
sora 2 pro ↗
Modified Source ↗
deepseek ↗
Modified Source ↗
google ↗
Modified Source ↗
meta ↗
Modified Source ↗
minimaxai ↗
Modified Source ↗
mistral ↗
Modified Source ↗
moonshot ai ↗
Modified Source ↗
openai ↗
Modified Source ↗
qwen ↗
Modified Source ↗
zai org ↗
Modified Source ↗
together inference engine v1 ↗
Modified Source ↗
deploy deepseek r1 at scale fast secure serverless apis and large scale together reasoning clusters ↗
Modified Source ↗
deploy deepseek r1 and distilled models securely on together ai ↗
Modified Source ↗
on demand dedicated endpoints ↗
Modified Source ↗
thunderkittens nvidia blackwell gpus ↗
Modified Source ↗
fine tuning api introducing long context training conversation data support and more configuration options ↗
Modified Source ↗
code sandbox ↗
Modified Source ↗
multimodal document rag with llama 3 2 vision and colqwen2 ↗
Modified Source ↗
together ai partners with meta to release meta llama 3 for inference and fine tuning ↗
Modified Source ↗
llama 2 7b 32k instruct ↗
Modified Source ↗
meta llama 3 1 ↗
Modified Source ↗
instant gpu clusters ↗
Modified Source ↗
finetuning ↗
Modified Source ↗
nvidia gb200 together gpu cluster 36k ↗
Modified Source ↗
nvidia hgx b200 with together kernel collection ↗
Modified Source ↗
tri dao flash attention ↗
Modified Source ↗
speculative decoding for high throughput long context inference ↗
Modified Source ↗
optimizing training workloads for gpu clusters ↗
Modified Source ↗
kimi k2 leading open source model now available on together ai ↗
Modified Source ↗
introducing the together enterprise platform ↗
Modified Source ↗
fastest inference for deepseek r1 0528 with nvidia hgx b200 ↗
Modified Source ↗
qwen 3 coder ↗
Modified Source ↗
together instant clusters ga ↗
Modified Source ↗
together chat ↗
Modified Source ↗
together inference engine 2 ↗
Modified Source ↗
together ai powers pioneers at nvidia gtc 2025 ↗
Modified Source ↗
introducing fine tuning platform ↗
Modified Source ↗
specexec ↗
Modified Source ↗
cartesia ↗
Modified Source ↗
runware ↗
Modified Source ↗
scb10x ↗
Modified Source ↗
20 exaflops gpu clusters ↗
Modified Source ↗
accelerate inference large scale workloads ↗
Modified Source ↗
adaptive learning speculator system atlas ↗
Modified Source ↗
ai agents to automate complex engineering tasks ↗
Faster inference enables up to 5x price reduction on Together API ↗
Modified Source ↗
batch api ↗
Modified Source ↗
batch inference api updates 2025 ↗
Modified Source ↗
bitdelta ↗
Modified Source ↗
cocktailsgd ↗
Modified Source ↗
code sandbox code interpreter ↗
Modified Source ↗
continued fine tuning ↗
Modified Source ↗
fine tuning llms for multi turn conversations a technical deep dive ↗
Modified Source ↗
fine tuning updates sept 2025 ↗
Modified Source ↗
long context fine tuning a technical deep dive ↗
Modified Source ↗
rag fine tuning ↗
Modified Source ↗
arcee ai ↗
Modified Source ↗
dippy ai ↗
Modified Source ↗
hedra ↗
Modified Source ↗
heroui ↗
Modified Source ↗
latent health ↗
Modified Source ↗
legionedge ↗
Modified Source ↗
scaled cognition ↗
Modified Source ↗
slingshot ai ↗
Modified Source ↗
vercept ↗
Modified Source ↗
washington post ↗
Modified Source ↗
xy ai labs ↗
Modified Source ↗
zomato ↗
Modified Source ↗
cursor ↗
Modified Source ↗
flux 3 ↗
Modified Source ↗
gpt image 2 ↗
Modified Source ↗
happyhorse 1 0 i2v ↗
Modified Source ↗
happyhorse 1 0 r2v ↗
Modified Source ↗
happyhorse 1 0 t2v ↗
Modified Source ↗
happyhorse 1 1 i2v ↗
Modified Source ↗
happyhorse 1 1 r2v ↗
Modified Source ↗
happyhorse 1 1 t2v ↗
Modified Source ↗
minimax speech 28 ↗
Modified Source ↗
mixtral instruct ↗
Modified Source ↗
qwen3 8 flash ↗
Modified Source ↗
rime arcana v3 ↗
Modified Source ↗
rime arcana v3 turbo ↗
Modified Source ↗
rime mist v3 ↗
Modified Source ↗
rime mist v3 omni ↗
Modified Source ↗
seedance 2 0 ↗
Modified Source ↗
whisper large v3 streaming ↗
Modified Source ↗
gtc berlin 2026 ↗
Modified Source ↗
nvidia nemotron 3 ultra ↗
Modified Source ↗
cartesia sonic ↗
Modified Source ↗
llm inference ↗
Modified Source ↗
how to fine tune llms ↗
Modified Source ↗
kv cache ↗
Modified Source ↗
rag vs fine tuning ↗
Modified Source ↗
what are llms ↗
Modified Source ↗
ai engineer europe 2026 ↗
Modified Source ↗
ai engineer worlds fair 2026 ↗
Modified Source ↗
humanx 2026 ↗
Modified Source ↗
icml 2026 ↗
Modified Source ↗
mlsys 2026 ↗
Modified Source ↗
nvidia gtc 2026 ↗
Modified Source ↗
raise 2026 ↗
Modified Source ↗
running open models in production a live walkthrough of our new inference platform ↗
Modified Source ↗
the ai conference 2026 ↗
Modified Source ↗
the science of speed ↗
Modified Source ↗
together table ai leaders nyc ↗
Modified Source ↗
together table ai natives ↗
Modified Source ↗
together table digital natives ↗
Modified Source ↗
NVIDIA H100 ↗
Modified Source ↗
kimi k26 ↗
Modified Source ↗
NVIDIA HGX B300 ↗
Modified Source ↗
deepseek v4 pro ↗
Modified Source ↗
flux 1 schnell 2 ↗
Modified Source ↗
google veo 3 0 audio ↗
Modified Source ↗
google veo 3 0 fast ↗
Modified Source ↗
google veo 3 0 fast audio ↗
Modified Source ↗
hidream i1 full ↗
Modified Source ↗
qwen3 coder 480b a35b instruct ↗
Modified Source ↗
a practitioners guide to testing and running large gpu clusters for training generative ai models ↗
Modified Source ↗
announcing the availability of openais open models on together ai ↗
Modified Source ↗
announcing together ai startup accelerator ↗
Modified Source ↗
announcing together custom models ↗
Modified Source ↗
api announcement ↗
Modified Source ↗
arcee ai ↗
Modified Source ↗
axiomatic agents ↗
Modified Source ↗
based ↗
Modified Source ↗
benchmarking language models using the together research computer ↗
Modified Source ↗
building an autonomous and open data scientist agent from scratch ↗
Modified Source ↗
chipmunk ↗
Modified Source ↗
clustermax gold ↗
Modified Source ↗
code interpreter ↗
Modified Source ↗
codesandbox acquisition together code interpreter ↗
Modified Source ↗
collinear simulations together evals ↗
Modified Source ↗
customized speculative decoding ↗
Modified Source ↗
decentralized training of foundation models in heterogeneous environments ↗
Modified Source ↗
deepcoder ↗
Modified Source ↗
dippy ai ↗
Modified Source ↗
direct preference optimization ↗
Modified Source ↗
dragonfly v1 ↗
Modified Source ↗
embeddings endpoint release ↗
Modified Source ↗
even better even faster quantized llms with qtip ↗
Modified Source ↗
evo ↗
Modified Source ↗
fine tune gpt oss models into domain experts together ai ↗
Modified Source ↗
fine tune small open source llms outperform closed models ↗
Modified Source ↗
fine tuning language models over slow networks using activation compression with guarantees ↗
Modified Source ↗
flash decoding for long context inference ↗
Modified Source ↗
flashattention 3 ↗
Modified Source ↗
flashattentionfandm ↗
Modified Source ↗
flashfftconv ↗
Modified Source ↗
flexgen high throughput generative inference of large language models with a single gpu ↗
Modified Source ↗
function calling json mode ↗
Modified Source ↗
h3 ↗
Modified Source ↗
how zomato built an ai customer support bot that doubled customer satisfaction ↗
Modified Source ↗
hungry hungry hippos towards language modeling with state space models ↗
Modified Source ↗
hyena hierarchy towards larger convolutional language models ↗
Modified Source ↗
large reasoning models fail to follow instructions during reasoning a benchmark study ↗
Modified Source ↗
linearizing llms with lolcats ↗
Modified Source ↗
llama 2 7b 32k ↗
Modified Source ↗
long context retrieval models with monarch mixer ↗
Modified Source ↗
mahadev konar svp infrastructure engineering ↗
Modified Source ↗
mamba 3b slimpj ↗
Modified Source ↗
medusa ↗
Modified Source ↗
minions ↗
Modified Source ↗
moaa ↗
Modified Source ↗
monarch mixer ↗
Modified Source ↗
neurips 2022 overcoming communication bottlenecks for decentralized training 12 ↗
Modified Source ↗
neurips 2022 overcoming communication bottlenecks for decentralized training 2 ↗
Modified Source ↗
nvidia cloud partner ↗
Modified Source ↗
nvidia h200 and h100 gpu cluster performance together kernel collection ↗
Modified Source ↗
nvidia nim ↗
Modified Source ↗
open deep research ↗
Modified Source ↗
openais new open gpt oss models vs o4 mini a real world comparison ↗
Modified Source ↗
openchatkit ↗
Modified Source ↗
openchatkit 016 ↗
Modified Source ↗
python sdk v1 ↗
Modified Source ↗
rag tutorial langchain ↗
Modified Source ↗
rag tutorial llamaindex ↗
Modified Source ↗
rag tutorial mongodb ↗
Modified Source ↗
redpajama 3b updates ↗
Modified Source ↗
redpajama 7b ↗
Modified Source ↗
redpajama data v2 ↗
Modified Source ↗
redpajama models v1 ↗
Modified Source ↗
redpajama training progress ↗
Modified Source ↗
redpajama v2 faq ↗
Modified Source ↗
releasing v1 of gpt jt powered by open source ai ↗
Modified Source ↗
seed funding ↗
Modified Source ↗
sequoia ↗
Modified Source ↗
series a ↗
Modified Source ↗
series a2 ↗
Modified Source ↗
snorkel partnership ↗
Modified Source ↗
snowflake artic llm ↗
Modified Source ↗
soc 2 compliance ↗
Modified Source ↗
sota search stack for llms ↗
Modified Source ↗
stanford open source software award ↗
Modified Source ↗
stripedhyena 7b ↗
Modified Source ↗
teal training free activation sparsity in large language models ↗
Modified Source ↗
the frontier is open ↗
Modified Source ↗
thunderkittens ↗
Modified Source ↗
together ai acquires refuel ai ↗
Modified Source ↗
together ai announcing 305m series b ↗
Modified Source ↗
together ai available aws marketplace to accelerate enterprise ai development ↗
Modified Source ↗
together ai expands in europe ↗
Modified Source ↗
together ai welcomes kai mak ↗
Modified Source ↗
together crusoe reduce carbon impact of generative ai ↗
Modified Source ↗
together moa ↗
Modified Source ↗
yaqa ↗
Modified Source ↗
afm 4 5b preview ↗
Modified Source ↗
apriel 1 5 15b thinker ↗
Modified Source ↗
apriel 1 6 15b thinker ↗
Modified Source ↗
arcee ai afm 4 5b ↗
Modified Source ↗
arcee ai arcee blitz ↗
Modified Source ↗
arcee ai arcee spotlight ↗
Modified Source ↗
arcee ai caller ↗
Modified Source ↗
arcee ai coder large ↗
Modified Source ↗
arcee ai maestro reasoning ↗
Modified Source ↗
arcee ai virtuoso large ↗
Modified Source ↗
arcee ai virtuoso medium ↗
Modified Source ↗
bge base en v1 5 ↗
Modified Source ↗
bge large en v1 5 ↗
Modified Source ↗
bytedance seedance 1 0 pro ↗
Modified Source ↗
bytedance seededit ↗
Modified Source ↗
cogito 109b moe ↗
Modified Source ↗
cogito 405b ↗
Modified Source ↗
cogito 671b moe ↗
Modified Source ↗
cogito 70b ↗
Modified Source ↗
dbrx instruct ↗
Modified Source ↗
deepseek r1 ↗
Modified Source ↗
deepseek r1 0528 throughput ↗
Modified Source ↗
deepseek r1 distilled llama 70b free ↗
Modified Source ↗
deepseek v3 1 ↗
Modified Source ↗
deepseek v3 2 exp ↗
Modified Source ↗
dreamshaper ↗
Modified Source ↗
exaone 3 5 32b instruct ↗
Modified Source ↗
exaone deep 32b ↗
Modified Source ↗
flux 1 canny pro ↗
Modified Source ↗
flux 1 dev ↗
Modified Source ↗
flux 1 kontext dev ↗
Modified Source ↗
flux 1 krea dev ↗
Modified Source ↗
flux 1 pro ↗
Modified Source ↗
flux 1 schnell ↗
Modified Source ↗
flux 1 schnell fixedres ↗
Modified Source ↗
flux 2 max ↗
Modified Source ↗
flux1 1 pro ↗
Modified Source ↗
gemini flash image 2 5 ↗
Modified Source ↗
glm 4 6 ↗
Modified Source ↗
gpt image 1 5 ↗
Modified Source ↗
gpt oss 20b ↗
Modified Source ↗
gryphe mythomax l2 lite 13b ↗
Modified Source ↗
gte modernbert base ↗
Modified Source ↗
hidream i1 dev ↗
Modified Source ↗
hidream i1 fast ↗
Modified Source ↗
ideogram 40 ↗
Modified Source ↗
kimi k2 0905 ↗
Modified Source ↗
kimi k2 5 ↗
Modified Source ↗
kimi k2 instruct ↗
Modified Source ↗
kimi k2 thinking ↗
Modified Source ↗
kling 1 6 pro ↗
Modified Source ↗
kling 2 0 master ↗
Modified Source ↗
lfm2 24b a2b ↗
Modified Source ↗
llama 2 3325f ↗
Modified Source ↗
llama 2 chat 13b ↗
Modified Source ↗
llama 2 chat 7b ↗
Modified Source ↗
llama 3 1 ↗
Modified Source ↗
llama 3 1 405b ↗
Modified Source ↗
llama 3 2 3b instruct turbo ↗
Modified Source ↗
llama 3 3 70b free ↗
Modified Source ↗
llama 3 70b instruct reference ↗
Modified Source ↗
llama guard 2 8b ↗
Modified Source ↗
llama guard 3 11b vision turbo ↗
Modified Source ↗
llama guard 3 8b ↗
Modified Source ↗
llama guard 7b ↗
Modified Source ↗
m2 bert 80m 2k retrieval ↗
Modified Source ↗
m2 bert 80m 32k retrieval ↗
Modified Source ↗
m2 bert 80m 8k retrieval ↗
Modified Source ↗
marin 8b instruct ↗
Modified Source ↗
minimax 01 director ↗
Modified Source ↗
minimax hailuo 02 ↗
Modified Source ↗
minimax m21 ↗
Modified Source ↗
ministral 3 3b instruct 2512 ↗
Modified Source ↗
ministral 3 8b instruct 2512 ↗
Modified Source ↗
mistral 7b instruct v0 2 ↗
Modified Source ↗
mistral beb7b ↗
Modified Source ↗
mixtral 8x7b v0 1 ↗
Modified Source ↗
multilingual e5 large instruct ↗
Modified Source ↗
mxbai rerank large v2 ↗
Modified Source ↗
mythomax l2 ↗
Modified Source ↗
openai whisper large v3 ↗
Modified Source ↗
pixverse v5 ↗
Modified Source ↗
qwen image edit ↗
Modified Source ↗
qwen2 5 7b instruct turbo ↗
Modified Source ↗
qwen3 235b a22b fp8 tput ↗
Modified Source ↗
qwen3 235b a22b thinking 2507 ↗
Modified Source ↗
qwen3 8 27b ↗
Modified Source ↗
qwen3 coder next ↗
Modified Source ↗
qwen3 next 80b a3b instruct ↗
Modified Source ↗
refuel llm 2 ↗
Modified Source ↗
refuel llm 2 small ↗
Modified Source ↗
rnj 1 instruct ↗
Modified Source ↗
seedance 2 5 ↗
Modified Source ↗
stable diffusion 3 ↗
Modified Source ↗
typhoon 2 8b instruct ↗
Modified Source ↗
typhoon2 1 gemma3 12b ↗
Modified Source ↗
uae large v1 ↗
Modified Source ↗
virtueguard text lite ↗
Modified Source ↗
voxtral mini 3b 2507 ↗
Modified Source ↗
wan 2 6 image ↗
Modified Source ↗
NVIDIA GB200 NVL72 ↗
Modified Source ↗
NVIDIA GB300 NVL72 ↗
Modified Source ↗
NVIDIA H200 ↗
Modified Source ↗
NVIDIA HGX B200 ↗
Modified Source ↗
bytedance ↗
Modified Source ↗
deep cogito ↗
Modified Source ↗
alibaba ↗
Modified Source ↗
cartesia ↗
Modified Source ↗
deepgram ↗
Modified Source ↗
ideogram ↗
Modified Source ↗
nvidia ↗
Modified Source ↗
rundiffusion ↗
Modified Source ↗
black forest labs ↗
Modified Source ↗
best practices to accelerate inference for large scale production workloads ↗
Modified Source ↗
40 new image and video models ↗
Modified Source ↗